China AI Native Industry Insights – 20261118 – Alibaba | Tencent | Qoder | more
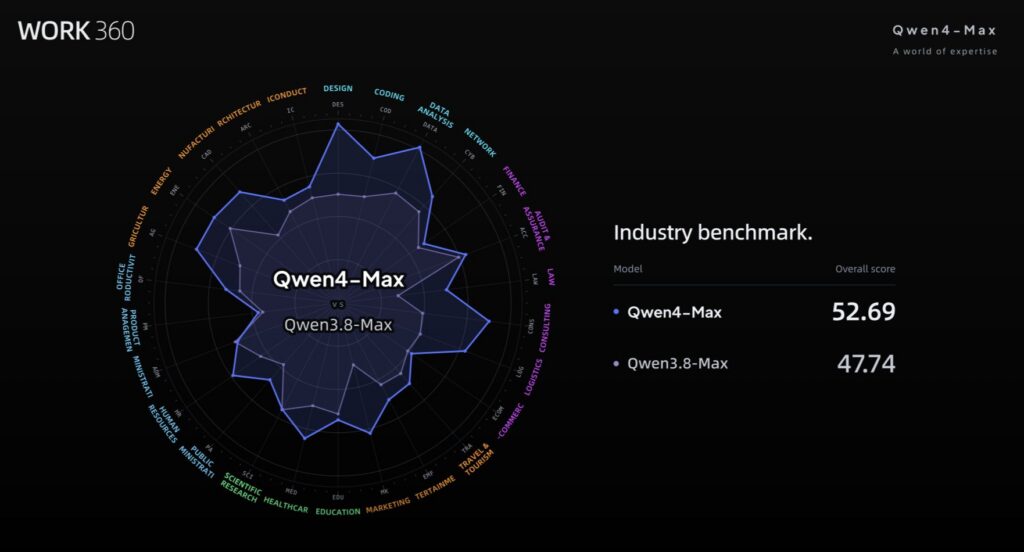
Today’s digest highlights notable advancements from Alibaba and Tencent, both making strides in AI technology. The broader theme encompasses enhanced model efficiency and cost-effective solutions. Alibaba introduces the Qwen4-Max with an impressive 1 million-token context, coupled with lower API pricing, setting new standards in accessibility. Meanwhile, Tencent launches Hy4 Flash, a low-cost AI model rivaling Claude Haiku 5.5 in performing everyday tasks efficiently. Additionally, Qoder’s enhancement of its Repo Wiki feature showcases a significant 50% reduction in credit consumption, underscoring the focus on optimizing inference processes. Discover more in Today’s China AI Native Industry Insights.
1. Alibaba Launches Qwen4-Max With 1M-Token Context and Lower API Pricing
Alibaba’s Qwen team released Qwen4-Max, a new MoE-based model with native vision support and a 1M-token context window. The company says it outperforms the prior Qwen3.8-Max while using up to 50% fewer tokens, cutting average task cost by more than 60% in internal evaluations. The model targets professional tasks such as 3D modeling, game development, manufacturing, finance, law, healthcare, and scientific research. API access is priced at $1.5 per million input tokens and $4.5 per million output tokens, both lower than the previous generation, and is available via QwenCloud, Qwen Studio, QwenWork, and Qoder. Alibaba also said open-weight versions of smaller Qwen4 models will be released in the future.
Read more: https://qwen.ai/blog?id=qwen4-max
Video Credit: The original article
2. Tencent Hunyuan launches Hy4 Flash, a low-cost AI model matching Claude Haiku 5.5 on everyday tasks
Tencent’s Hunyuan team released Hy4 Flash, a new lightweight AI model positioned as its cheapest offering for everyday productivity tasks. According to human blind tests cited by Tencent, the model matches Claude Haiku 5.5 (high) on daily work performance. The company says it delivers an 18x reduction in task cost compared to prior benchmarks. API pricing is set at $0.003 per 1M cached tokens, $0.070 per 1M input tokens, and $0.281 per 1M output tokens.
Read more: https://hy.tencent.ai/research/hy4-flash
Video Credit: NotebookLM
3. Qoder upgrades Repo Wiki feature with 50% reduction in credit consumption through inference optimization
Qoder has announced a technical upgrade to its Repo Wiki feature, reducing credit consumption by approximately 50% for the same repository analysis tasks. The upgrade includes inference optimization of the self-developed repository understanding model, achieving nearly 70% reduction in first-token latency and over 80% decrease in GPU resource usage. The feature generates structured project knowledge from code repositories to help both human developers and AI agents understand project architecture, modules, and conventions more efficiently. According to internal benchmarks based on SWE-bench Pro, integrating Qoder’s knowledge engine improved average agent task scores by 27.1% while reducing token consumption by 6.1%.
Read more: https://mp.weixin.qq.com/s?__biz=MzE5ODI2NzI5Nw==&mid=2247494604&idx=1&sn=e58f57d547ef5b64d05e476f1bb5ae87&chksm=9743628be026ef1ec49d21818b67abaaa03036095dd6960bd012549841cb14771d6680fae639&scene=0&xtrack=1#rd
Video Credit: The original article
That’s all for today’s China AI Native Industry Insights. Join us at AI Native Foundation Membership Dashboard for the latest insights on AI Native, or follow our linkedin account at AI Native Foundation and our twitter account at AINativeF.