AI Native Daily Paper Digest – 20261014 – Jeva | VideoJev | GreenWAM
Today’s digest highlights notable contributions from GPT and Claude, focusing on advancements in long-context attention capabilities. The collection emphasizes innovations in addressing computation efficiency and model scalability, featuring methods like Recursive Attention Circuits and results such as a 15% speed increase in processing extensive datasets. A remarkable finding is that the use of these new approaches led to significant gains in benchmark scores, with some models achieving up to a 20% improvement in accuracy over previous iterations. These advancements indicate a closer step toward practical, real-time applications in dynamic environments.
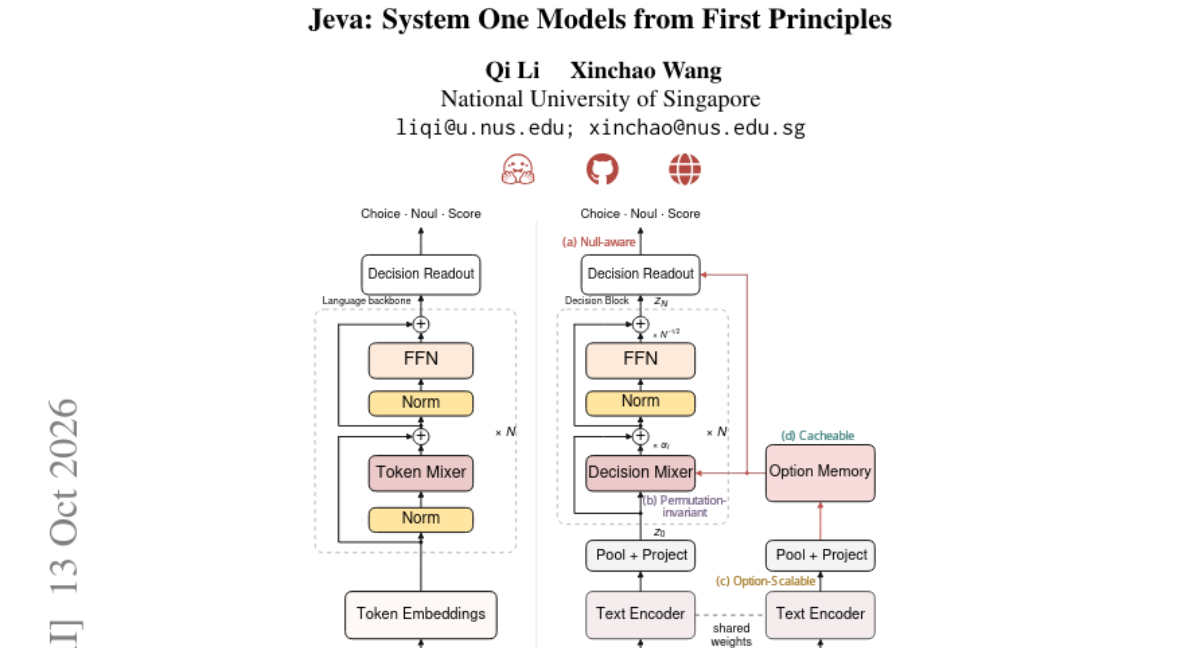
1. Jeva: System One Models from First Principles
🔑 Keywords: System one models, decision-making, Jeva, decision-native architecture, null detection
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The research aims to propose a decision-native architecture (Jeva) that addresses four structural requirements often overlooked in current decision-making models.
🛠️ Research Methods:
– The Jeva architecture incorporates a shared encoder and a compact decision stack to handle request and option representation, offering permutation-equivariant probabilities and supporting variable-size candidate sets.
💬 Research Conclusions:
– Jeva demonstrates strong performance in typed-decision making with effective null detection, maintaining decision integrity across permutations, and reducing latency through cross-request reuse.
👉 Paper link: https://huggingface.co/papers/2610.18773
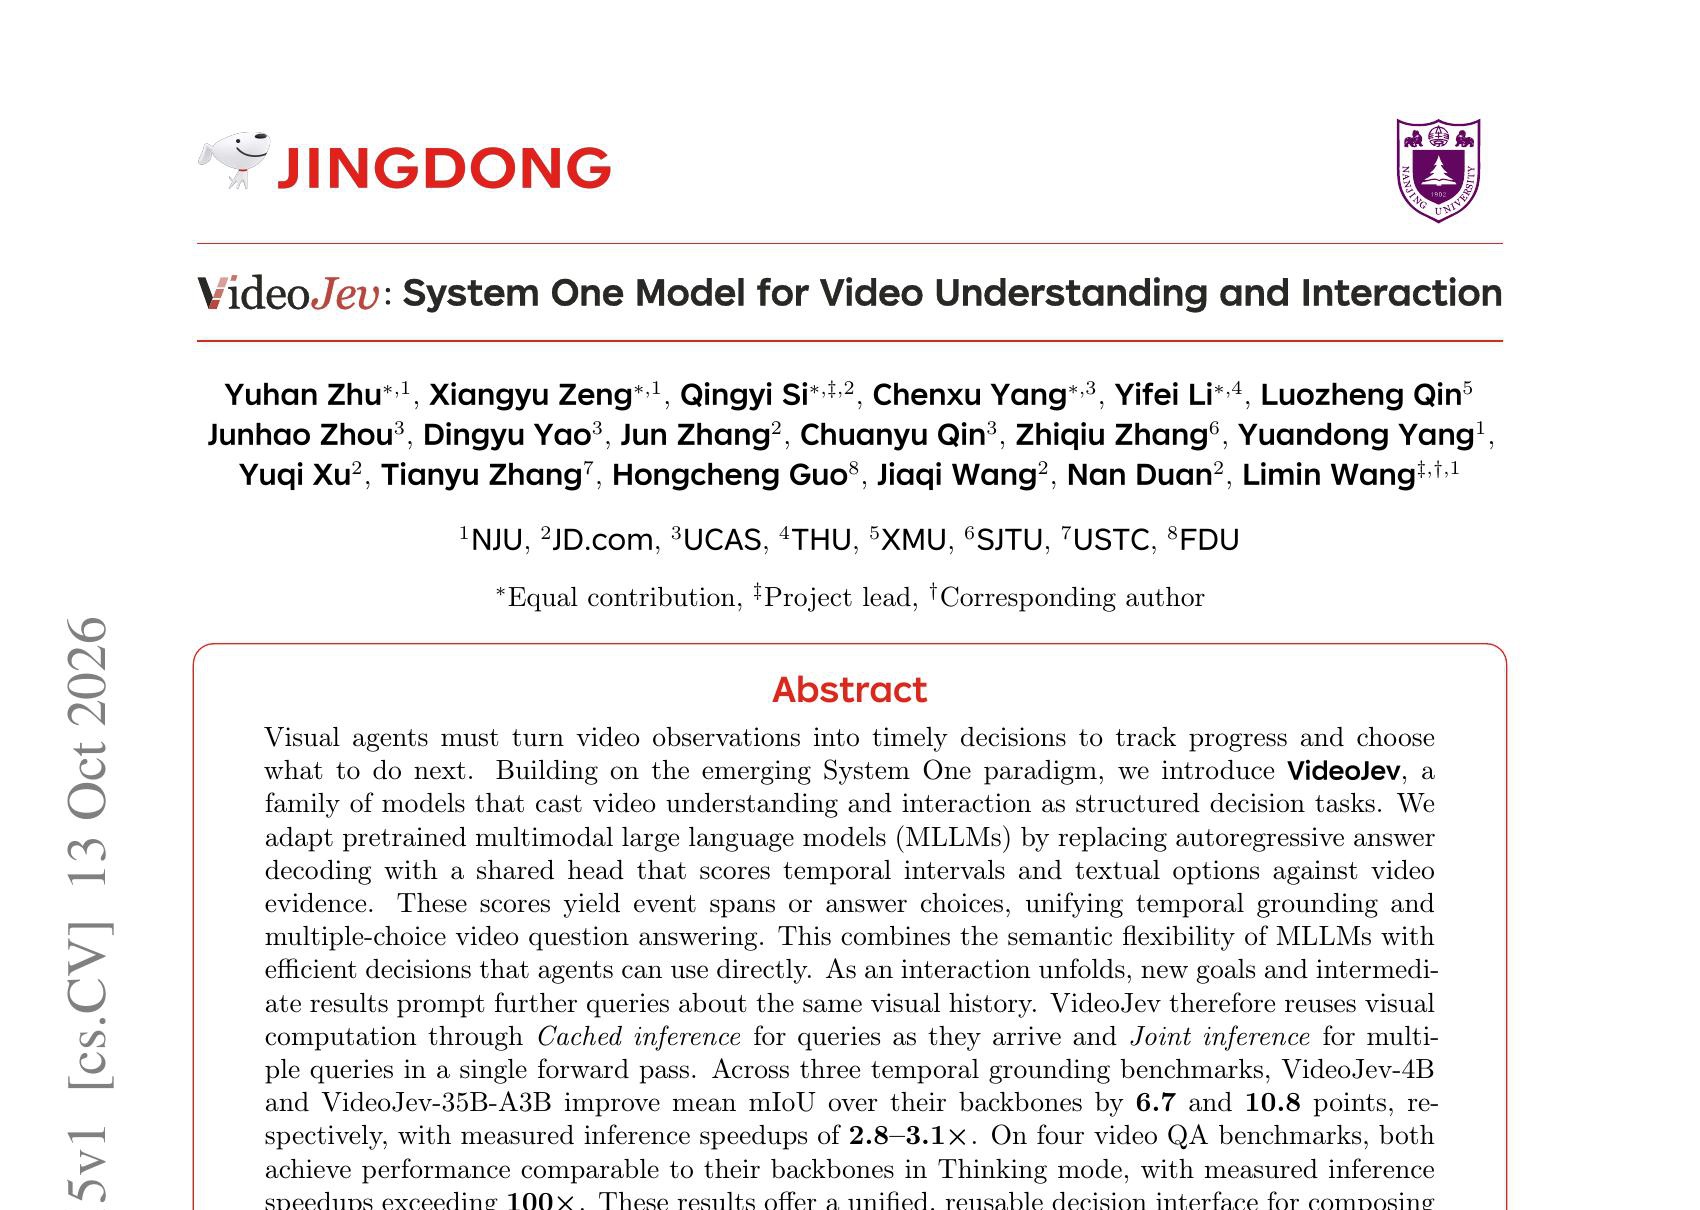
2. VideoJev: System One Model for Video Understanding and Interaction
🔑 Keywords: VideoJev, System One paradigm, multimodal large language models, temporal grounding, video question answering
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– Introduce VideoJev models aiming to enhance video understanding and interaction by structuring these as decision tasks.
🛠️ Research Methods:
– Adaptation of pretrained multimodal large language models by implementing a shared scoring head to evaluate temporal intervals and textual options against video data.
– Incorporation of Cached inference and Joint inference to improve computational efficiency as events unfold.
💬 Research Conclusions:
– VideoJev models demonstrated significant improvements in mean mIoU for temporal grounding tasks and achieved inference speedups.
– For video QA benchmarks, they matched performance of original models while achieving substantial inference speed improvements, suggesting efficient and reusable decision-making interfaces.
👉 Paper link: https://huggingface.co/papers/2610.18615
3. GreenWAM: A World Foundation Model for Robotics
🔑 Keywords: GreenWAM, world model, policy, zero-shot, LIBERO-plus
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– To determine if a single robot world model can serve both predictive and policy roles across different robot bodies.
🛠️ Research Methods:
– Development of the GreenWAM, a world foundation model for robotics, using a shared anatomical action space across 20 robot families, joint training on these families, and policies that separate action experts from the generator.
💬 Research Conclusions:
– GreenWAM excelled in trajectory, depth, and 3D accuracy on benchmarks like WorldArena 1.0 and performed well on the RoboTwin 2.0 leaderboard as a policy. The model proved effective when adapted to real humanoids, showing high zero-shot LIBERO-plus success, and demonstrated the importance of robot specialization and early action expert integration for improved performance.
👉 Paper link: https://huggingface.co/papers/2610.18774
4. Harness^2: Recursive Agent Harnessing for an Open World
🔑 Keywords: Recursive self-improvement, Harness^2, Propose-Probe-Compose, GLM-5, Gemini 3.5 Flash
💡 Category: AI Systems and Tools
🌟 Research Objective:
– Introduce a recursive agent harnessing framework, Harness^2, that overcomes challenges of deploying Recursive self-improvement in open-world settings.
🛠️ Research Methods:
– Implement two levels of recursion: task-level recursion using Propose-Probe-Compose steps and harness-level recursion for continual improvement.
💬 Research Conclusions:
– Harness^2 improves model performance (GLM-5 and Gemini 3.5 Flash), achieving gains of up to 11.5 points on WorkBuddy-Bench, 4.5 on JobBench, and 11.8 percentage points on LAB with increased recursion.
👉 Paper link: https://huggingface.co/papers/2610.14224
5. TPPO: Tracking-Value PPO For Language Model Reasoning
🔑 Keywords: Proximal Policy Optimization, Reinforcement Learning, Bayesian Decomposition, Mathematical Reasoning, Value Evolution
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study aims to improve the capability of Proximal Policy Optimization (PPO) in reinforcement learning for language-model reasoning by better tracking token-level credit under sparse terminal rewards.
🛠️ Research Methods:
– The authors propose a novel method called Tracking-Value PPO (TPPO) which uses Bayesian decomposition and additive updates in log-odds space to model value evolution. This method is parameterized by summing position-wise scalar outputs into value logits, learned through terminal-outcome supervision.
💬 Research Conclusions:
– Tracking-Value PPO increases mathematical reasoning scores by 7.0 to 8.4 points over PPO, enhances out-of-distribution generalization, and provides more accurate value evolution tracking and reliable advantage estimates. The method’s effectiveness extends to various models and tasks, with code available on GitHub.
👉 Paper link: https://huggingface.co/papers/2610.16794
6. X-Ragent: Tool-Augmented Reinforcement Learning for Evidence-Grounded Chest X-Ray Reasoning
🔑 Keywords: X-Ragent, Chest X-ray (CXR), reinforcement learning, AI in Healthcare, evidence-grounded reasoning
💡 Category: AI in Healthcare
🌟 Research Objective:
– The goal is to improve CXR interpretation by integrating tool-augmented reinforcement learning for evidence-grounded reasoning, ensuring only valid measurements are applied to prevent incorrect diagnosis.
🛠️ Research Methods:
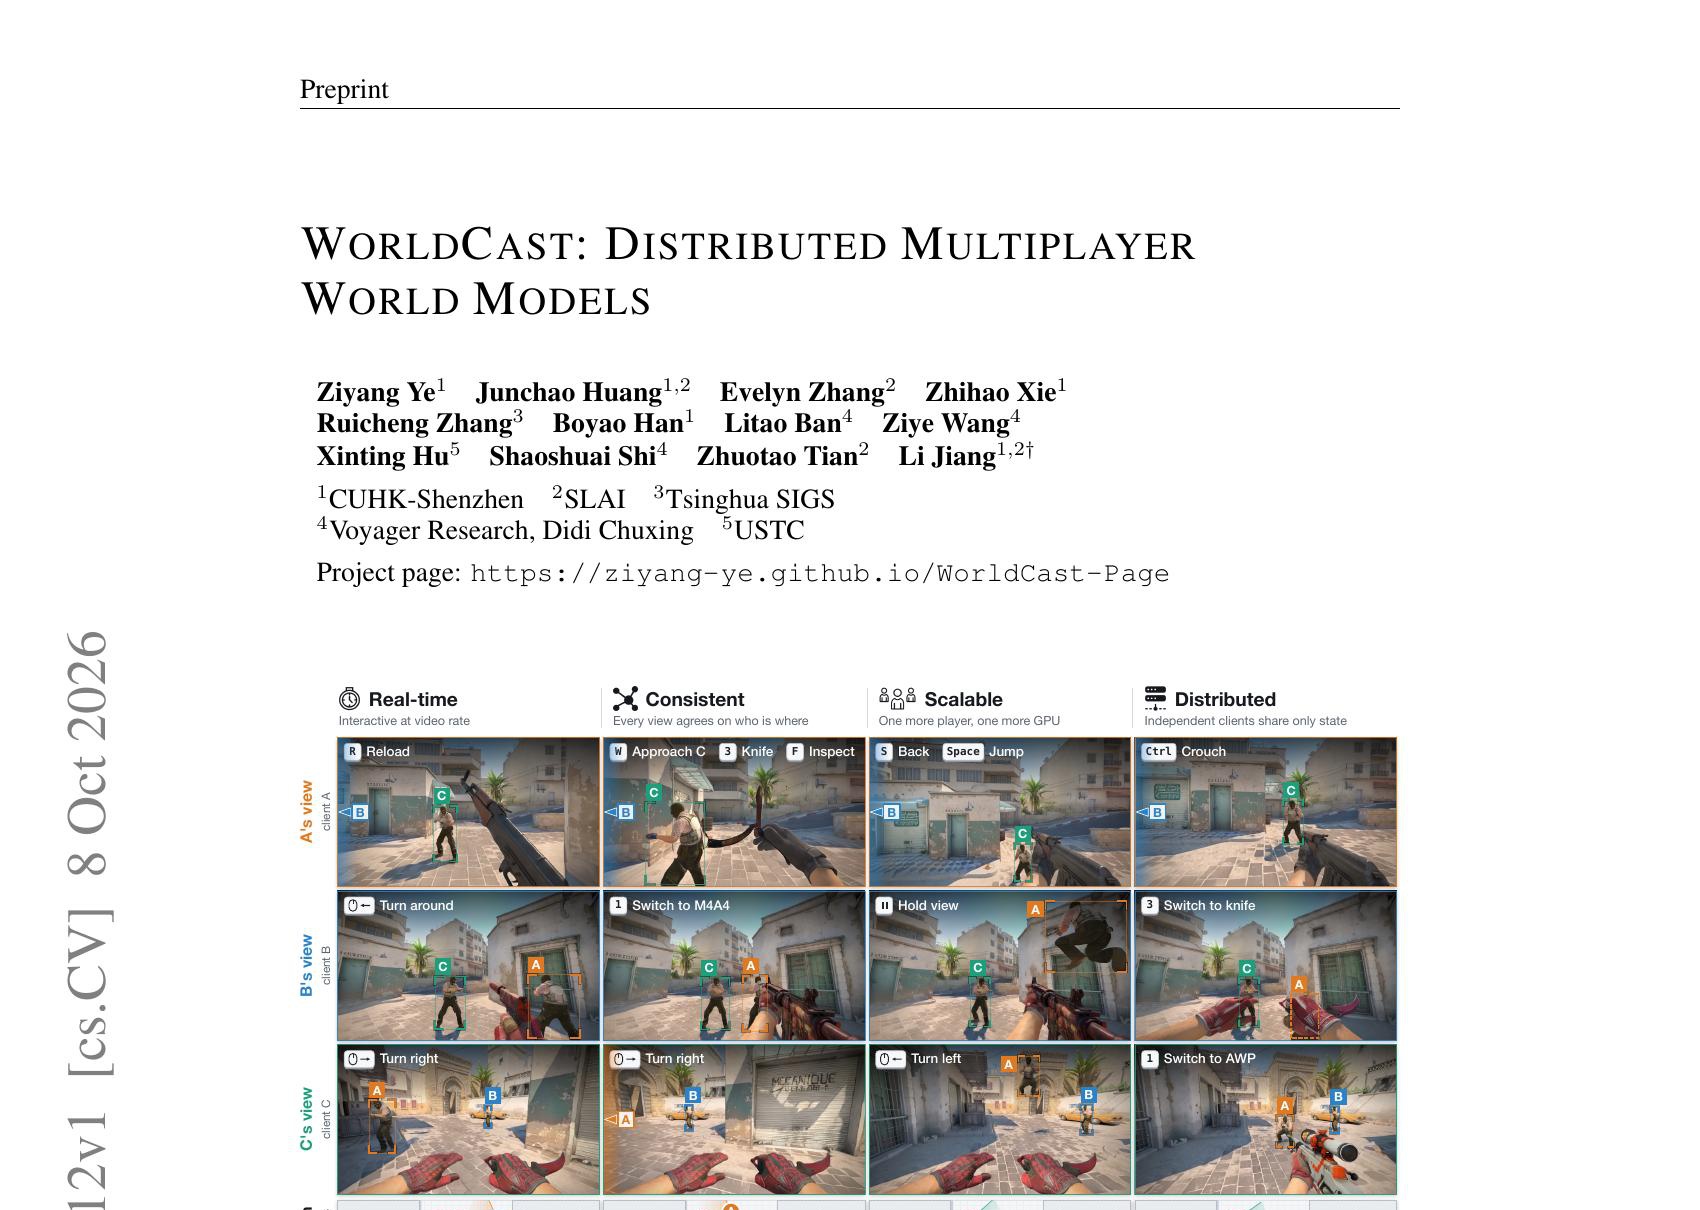
– Introduction of X-Ragent, a post-training framework, and development of Rad-CoT corpus to initialize Qwen3-VL-8B via supervised fine-tuning. Optimization is achieved through Group Relative Policy Optimization (GRPO) using an accuracy-gated reward system.
💬 Research Conclusions:
– X-Ragent demonstrated significant improvement across CXR benchmarks, including an 8.6-point improvement on ChestAgentBench, by selectively seeking evidence and allowing only valid measurements.
👉 Paper link: https://huggingface.co/papers/2610.16811
7. WorkRover: Scaling Long-Horizon Cowork Agent Training Via Recursive Environment Evolution
🔑 Keywords: Reinforcement Learning, Long-Horizon Agents, WorkRover, Iterative Refinement
💡 Category: Reinforcement Learning
🌟 Research Objective:
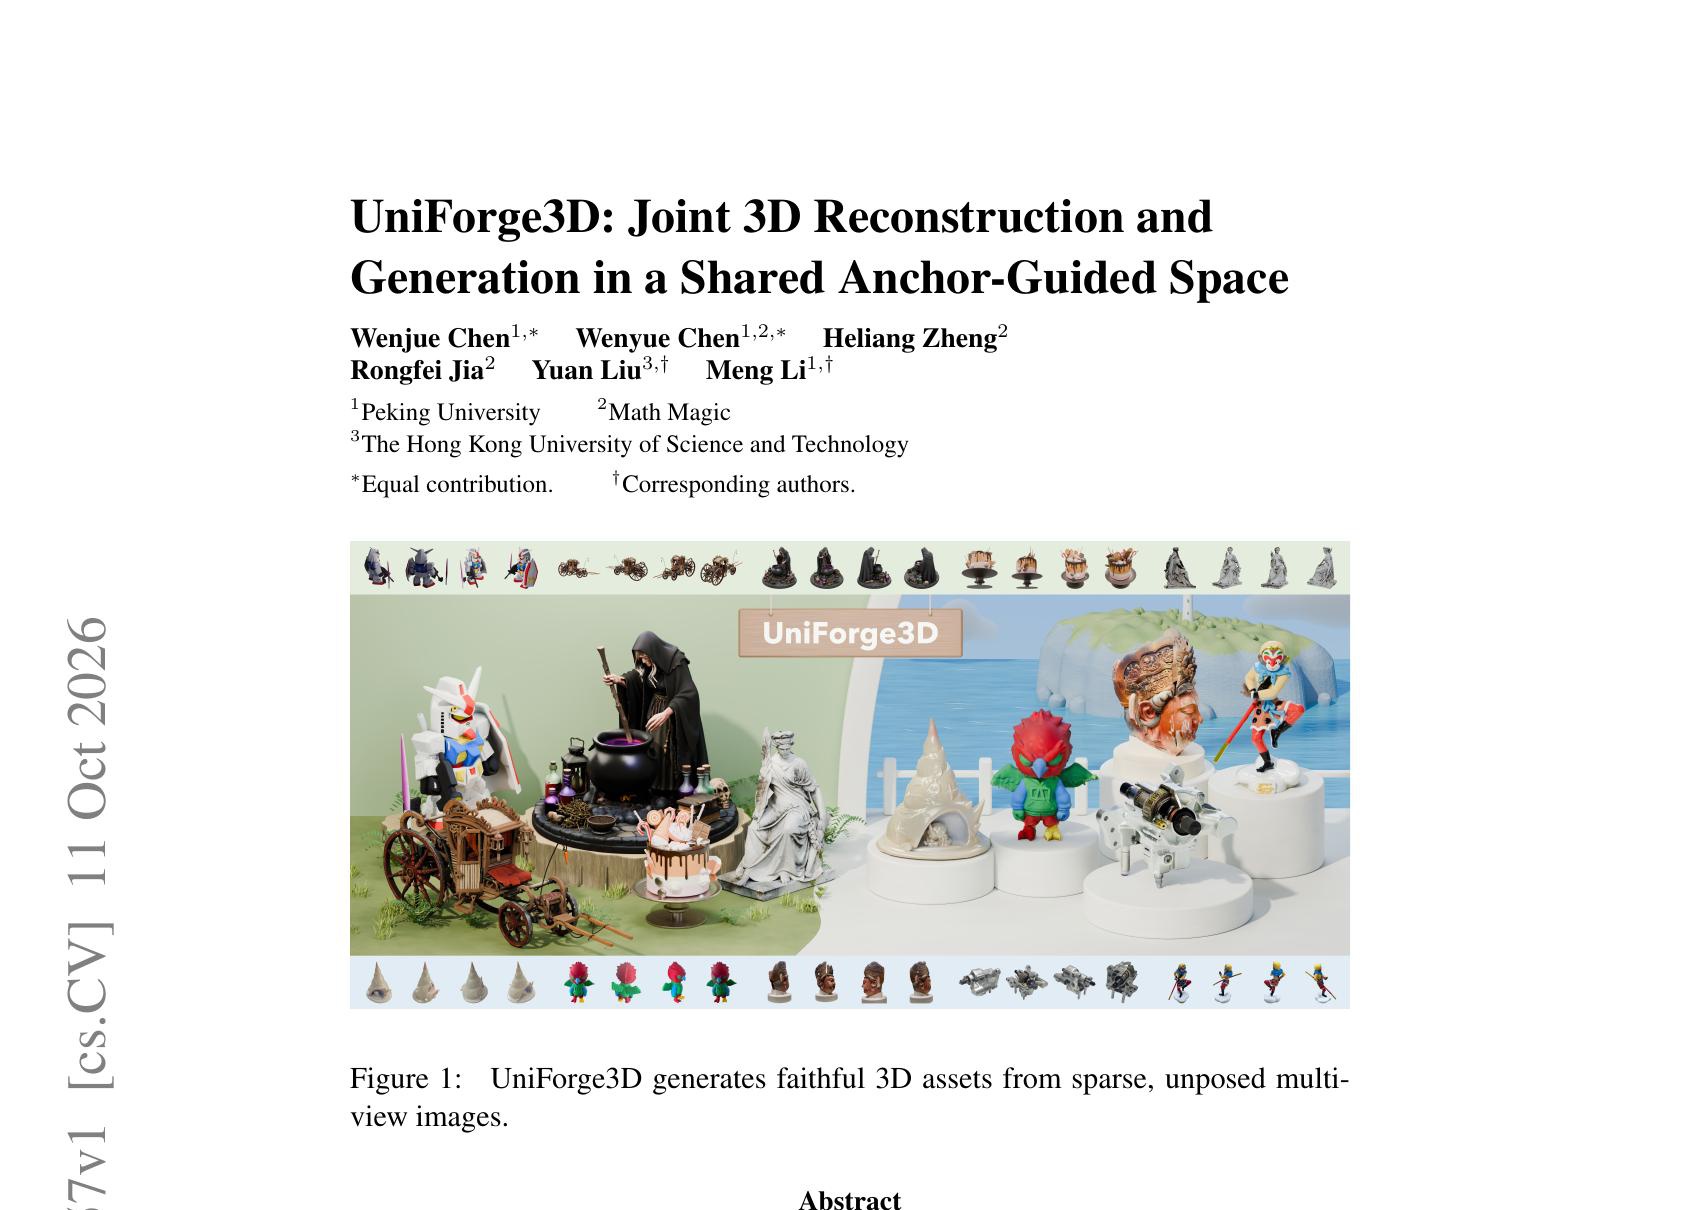
– The objective is to scale interactive environments for training long-horizon agents through reinforcement learning by iterative refinement of tasks and their contexts.
🛠️ Research Methods:
– Introduction of WorkRover framework using recursive environment evolution for training agents.
– Deployment of Factorial Compatibility Replay (FCR) and Verifier-to-Turn Credit Assignment (VTCA) to enhance environment evolution and training signals.
💬 Research Conclusions:
– Post-training results with WorkRover demonstrate significant improvements over Qwen3.5-35B-A3B on various benchmarks, indicating its effectiveness for scalable training of agents.
👉 Paper link: https://huggingface.co/papers/2610.18067
8. LeWAM: End-to-End World and Action Modeling with JEPAs
🔑 Keywords: JEPA, LeWAM, latent world models, control policy, visual planning
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study introduces LeWAM, a joint-embedding predictive architecture for efficiently executing and planning control policies without the need for pixel reconstruction.
🛠️ Research Methods:
– LeWAM utilizes a joint training objective focused on next latent state prediction and action flow matching, alongside an isotropic Gaussian constraint on the latent state.
💬 Research Conclusions:
– LeWAM significantly improves the success rate in visual planning tasks, increasing efficiency in contact-rich and long-horizon tasks, while also demonstrating competitive performance with established methods in behavior cloning tasks.
👉 Paper link: https://huggingface.co/papers/2610.12818
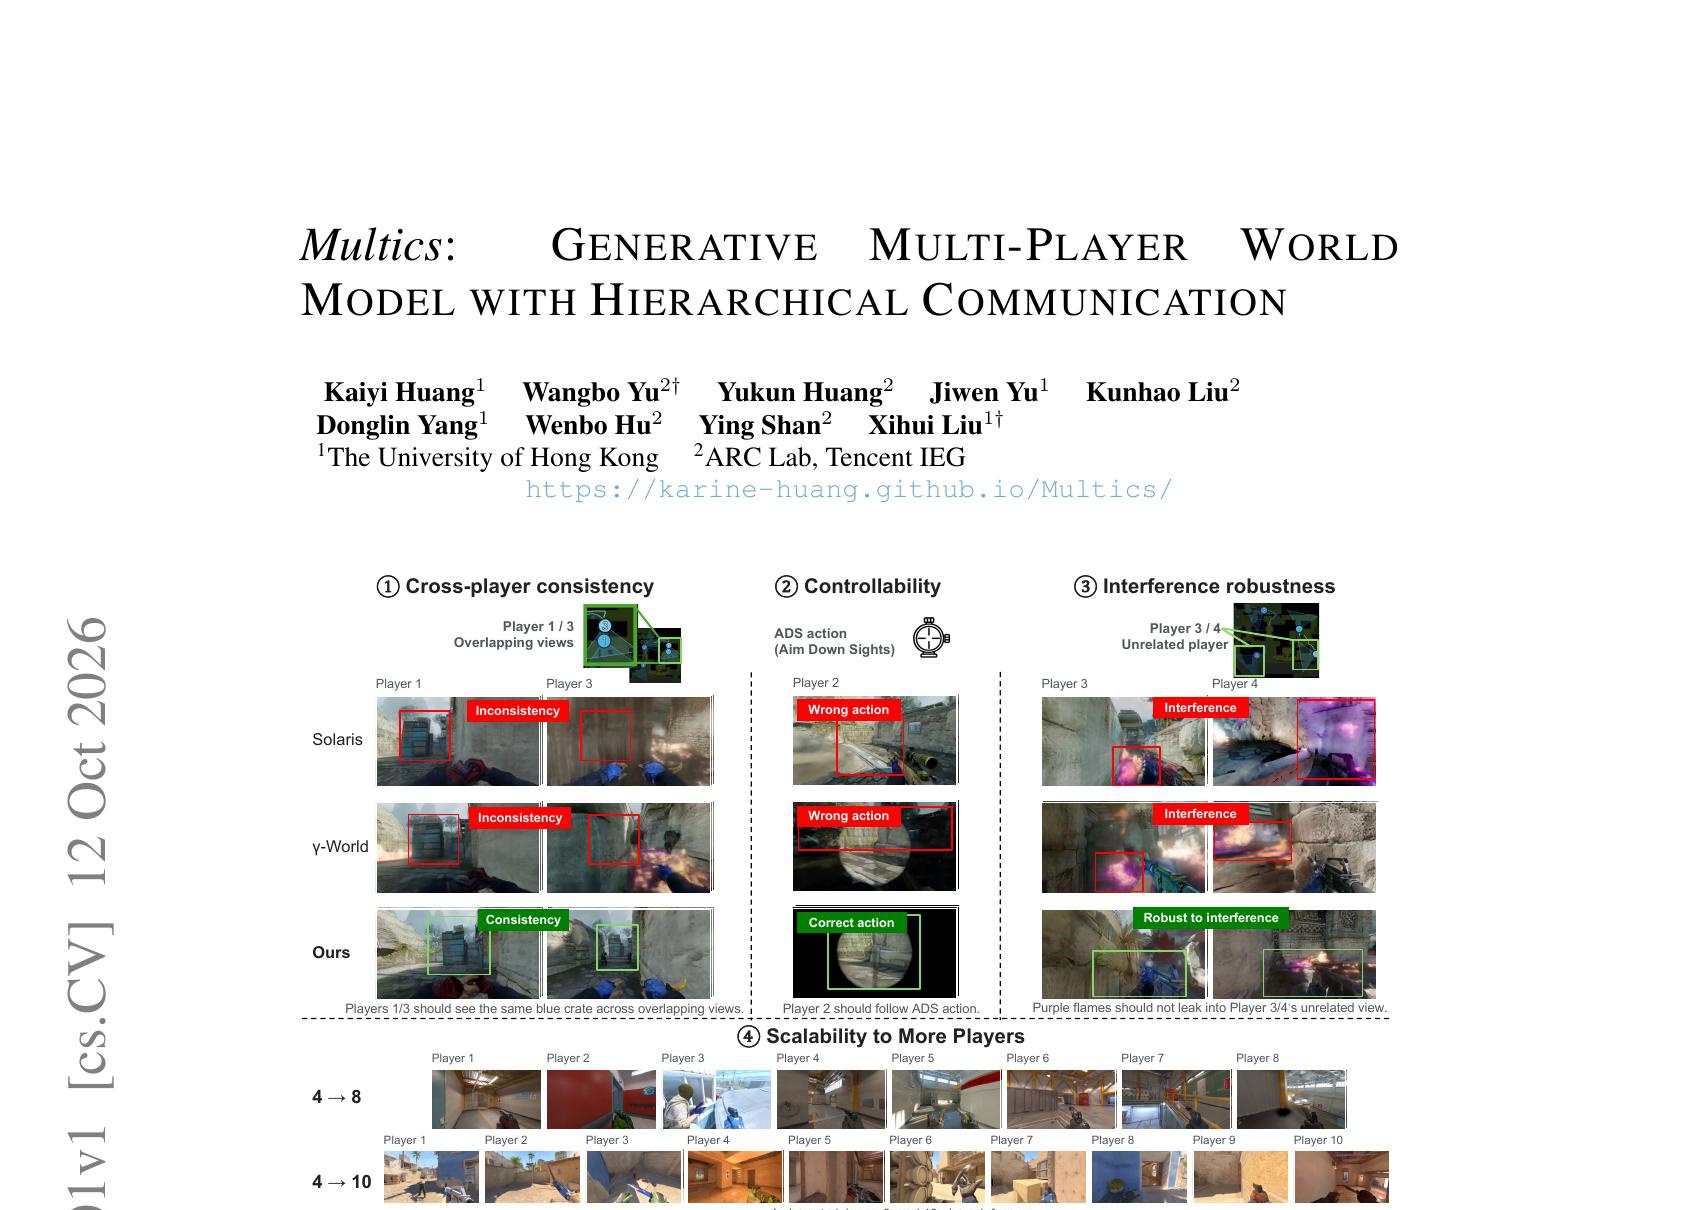
9. Multics: Generative Multi-Player World Model with Hierarchical Communication
🔑 Keywords: Multi-player interactive world models, hierarchical communication, group-token parameters, cross-player consistency, state-of-the-art performance
💡 Category: Generative Models
🌟 Research Objective:
– To develop a multi-player video generation framework, named Multics, that improves robustness and scalability by introducing a hierarchical communication structure.
🛠️ Research Methods:
– Implementing hierarchical levels of communication (player, group, and global) using group tokens in self-attention for structured information exchange, and employing budget-constrained dynamic grouping based on camera trajectories.
💬 Research Conclusions:
– Multics achieves state-of-the-art performance in scenarios with 4- and 6-player settings, demonstrating enhanced cross-player consistency, controllability, and robustness against interference, with successful generalization to settings with more players without additional retraining.
👉 Paper link: https://huggingface.co/papers/2610.17201
10. Last Secure Code Benchmark: Is the Code You Vibe Secure?
🔑 Keywords: AI coding agents, secure code generation, Last Secure Code Benchmark, vulnerabilities, vibe-coding
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The paper aims to evaluate the security of code generated by AI coding agents using the Last Secure Code Benchmark, which assesses secure code generation.
🛠️ Research Methods:
– The authors developed a benchmark from 150 real vulnerabilities and 450 tasks across seven languages, evaluating code generation using both functional and hidden security tests without explicitly mentioning security in the specifications.
💬 Research Conclusions:
– While 73.6% to 91.3% of tasks pass functionally across six different coding agents, only 25.1% of the strongest agent’s code outputs are deemed both functional and secure. The study highlights security concerns, with the best model passing only 12% of vulnerability scenarios.
👉 Paper link: https://huggingface.co/papers/2610.14766
11. SALD: Self-Referenced Advantage Learning for Diffusion Models
🔑 Keywords: Self-referenced training, Diffusion models, Advantage-Guided Diffusion, Temporal Advantage Memory, Spectral Advantage Decomposition
💡 Category: Generative Models
🌟 Research Objective:
– The research aims to explore how diffusion models can utilize self-referenced training signals without needing external demonstrations or teacher networks.
🛠️ Research Methods:
– Introduction of SALD, a self-referenced training framework that evaluates image-caption pairs at different noise levels using the same model. Utilization of Advantage-Guided Diffusion (AGD), Temporal Advantage Memory (TAM), and Spectral Advantage Decomposition (SAD) to adapt training objectives and construct weights.
💬 Research Conclusions:
– The proposed method demonstrated consistent improvements in generation quality across multiple architectures and datasets, effectively quantified through component-wise ablations.
👉 Paper link: https://huggingface.co/papers/2610.01496
12. APEX: Asynchronous Prefix Denoising for Extreme Compression
🔑 Keywords: APEX, Asynchronous Prefix Denoising, Latent Compression, ImageNet-512
💡 Category: Generative Models
🌟 Research Objective:
– The study introduces APEX, a method to resolve the reconstruction-generation dilemma in extreme latent compression by using asynchronous prefix denoising.
🛠️ Research Methods:
– A hierarchical latent space is structured where channel prefixes are ordered from structure to detail, with a shared denoiser generating them locally in staggered times without increasing token count.
💬 Research Conclusions:
– APEX demonstrates superior performance compared to existing methods in terms of compression rates on ImageNet-512, excelling particularly at 64x and 128x compression. APEX also performs better than a 256-token model across various computational budgets, showing greater improvements with reduced compute.
👉 Paper link: https://huggingface.co/papers/2610.12843
13. VEDJE: Video-Efficient Discriminative Joint Encoder for Scalable Video-Text Retrieval
🔑 Keywords: VEDJE, Video Retrieval, Compressed Cache, Feature-Change Prediction, VideoCLIP-XL
💡 Category: Computer Vision
🌟 Research Objective:
– The main goal is to enhance video retrieval by compressing rich video representations within sampled frames and maintaining their distinctiveness in a reusable cache.
🛠️ Research Methods:
– Utilization of VEDJE to compress features with sampling and feature-change prediction to aid retrieval without increasing query time effort.
💬 Research Conclusions:
– VEDJE demonstrated improved R@1 scores over matched first-stage retrievers across several datasets, maintaining high accuracy even with significantly reduced cache size.
👉 Paper link: https://huggingface.co/papers/2610.11850
14. Data-Centric Recursive Self-Improvement for Navigation via Policy-Synchronized Language-Action Dual Bootstrapping
🔑 Keywords: Vision-language navigation, Language supervision, Data-centric recursive self-improvement, Spatial understanding
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– To improve vision-language navigation through a data-centric recursive self-improvement framework, integrating language-action dual bootstrapping for instruction following and generation.
🛠️ Research Methods:
– A shared model approach is utilized where vision-language-to-action and vision-action-to-language tasks are integrated.
– The framework progressively processes unlabeled trajectories and updates based on generated instructions and evaluations.
💬 Research Conclusions:
– RSI-Nav achieves high success rates on benchmarks R2R-CE and RxR-CE, enhances instruction-generation utility, and modestly improves spatial understanding.
👉 Paper link: https://huggingface.co/papers/2610.15782
15. Self-Distillation with Verbal Regularization
🔑 Keywords: On-policy self-distillation, Large language model, Privileged information, Verbal regularization
💡 Category: Natural Language Processing
🌟 Research Objective:
– To address the challenge of bias in supervisory cues caused by privileged information in large language model training through the introduction of verbal regularization (VRSD).
🛠️ Research Methods:
– The study employs self-distillation techniques where a language model learns from a teacher model conditioned on privileged information, and introduces verbal regularization to moderate the teacher’s influence on privileged information.
💬 Research Conclusions:
– The introduction of VRSD significantly improves Pass@1 scores in most model-task settings and maintains higher token entropy compared to traditional OPSD methods.
👉 Paper link: https://huggingface.co/papers/2610.16354
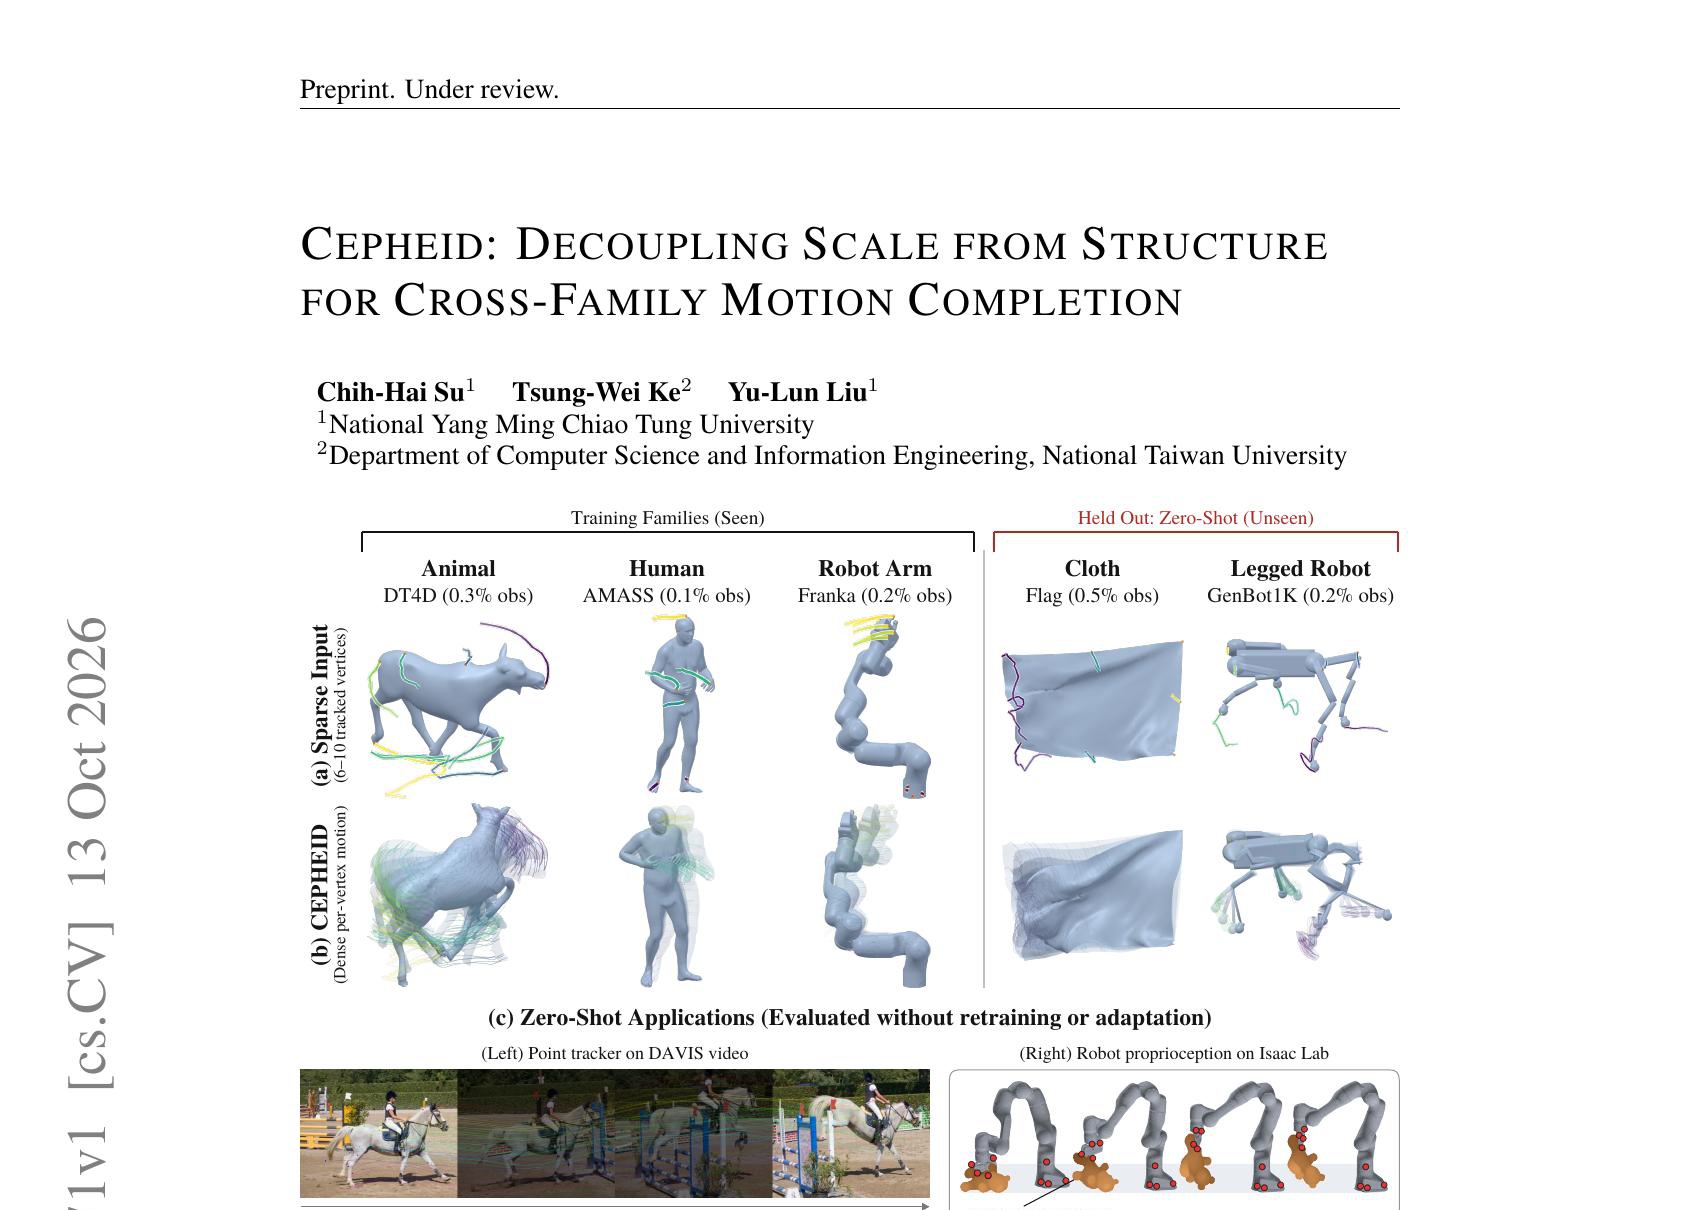
16. Cepheid: Decoupling Scale from Structure for Cross-Family Motion Completion
🔑 Keywords: Sparse-to-dense motion completion, Residual priors, Dimensionless prior, Harmonic extension
💡 Category: Computer Vision
🌟 Research Objective:
– The research aims to improve sparse-to-dense motion completion by developing a model that performs better than parameter-free harmonic extension, across different geometry families without additional retraining.
🛠️ Research Methods:
– The authors propose a unified model that separates residual structure from physical scale, using a dimensionless prior and a lightweight correction fitted only on training data sources.
💬 Research Conclusions:
– The proposed model consistently outperforms harmonic extension techniques across a wide range of geometry families, including unseen scenarios such as cloth, legged bodies, and animal video tracking, illustrating its robustness and applicability to various domains.
👉 Paper link: https://huggingface.co/papers/2610.18871
17. VIEWCRAFT: Evolving What Multimodal Agents See and How They Read It
🔑 Keywords: Reusable skills, ViewCraft, Multimodal agents, Evidence interface, Task score
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– The study introduces ViewCraft, a system designed to enhance multimodal agents by evolving an executable evidence interface and its reading procedure without the need to update model weights.
🛠️ Research Methods:
– The system utilizes failure traces to guide revisions, employs replay and paired evaluation to maintain useful changes, and incorporates interface projection for recovering visual edits. The interface selects and organizes observations while the reader interprets these views.
💬 Research Conclusions:
– ViewCraft significantly improves task performance, showcasing a 6.1 point increase in task score over direct execution across eight benchmarks. It also reduces input token usage by 8%-15% on multi-source tasks, indicating efficient evidence construction and reading as a coupled skill.
👉 Paper link: https://huggingface.co/papers/2610.15915
18. EgoExplorer: A Vision-Motion-Touch Observatory for Human Loco-Manipulation In Situ
🔑 Keywords: Humanoid loco-manipulation, EgoExplorer, Multimodal generation, Sensor calibration
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– The study aims to enhance the understanding of humanoid loco-manipulation by gathering comprehensive data from human demonstrations using the innovative EgoExplorer system.
🛠️ Research Methods:
– Employing a wearable capture system to record a 100-hour dataset that aligns egocentric video with whole-body motion, finger articulation, and tactile observations.
– Development of the Calibrate-Complete-Constrain pipeline to improve motion inference accuracy through reusable calibration, temporal priors, and layered constraints.
💬 Research Conclusions:
– The proposed method significantly reduces body-point error by 71.9% compared to existing baselines and shows improvements in hand stability and contact estimation.
👉 Paper link: https://huggingface.co/papers/2610.18872
19. ReTerm: Recovery Training for Self-Improving Terminal Agents
🔑 Keywords: Terminal agents, ReTerm, Reinforcement Learning, Self-recovery, Qwen3.5-9B
💡 Category: Reinforcement Learning
🌟 Research Objective:
– Introduce ReTerm, a terminal agent trained to recover from its failed tasks and improve its performance autonomously.
🛠️ Research Methods:
– Developed ReTerm-GRPO, an online RL algorithm to create multiple self-recovery attempts from failure states.
– Constructed a custom data pipeline resulting in the ReTerm-10K dataset for training.
💬 Research Conclusions:
– ReTerm-9B model achieves a significant improvement in task success rate, with 34.8% Pass@1 on Terminal-Bench 2.0, surpassing the base model by 14.6 points.
– Demonstrates consistently higher recovery rates across various error categories compared to standard GRPO training.
👉 Paper link: https://huggingface.co/papers/2610.18484
20. Fish Audio Drama 3 Technical Report
🔑 Keywords: Speech Generation, Multi-Character Scenes, Inference Efficiency, Drama 3, Mixture-of-Experts
💡 Category: Generative Models
🌟 Research Objective:
– Introduce Fish Audio Drama 3, a model for generating directed speech performances from text.
🛠️ Research Methods:
– Utilizes a 35B-parameter mixture-of-experts architecture, activating 3B parameters per token.
– Employs a hybrid linear-attention backbone and a new codebook multi-token-prediction audio decoder.
– Training involves a three-stage pre-training recipe, instruction fine-tuning, and large-batch reinforcement learning.
💬 Research Conclusions:
– Drama 3 can handle multi-turn revision, scene dubbing, editing by infilling, and streaming text input within a single model.
– Achieves high inference efficiency with 271 frames per second on H200, surpassing its predecessor despite a larger parameter size.
👉 Paper link: https://huggingface.co/papers/2610.18010
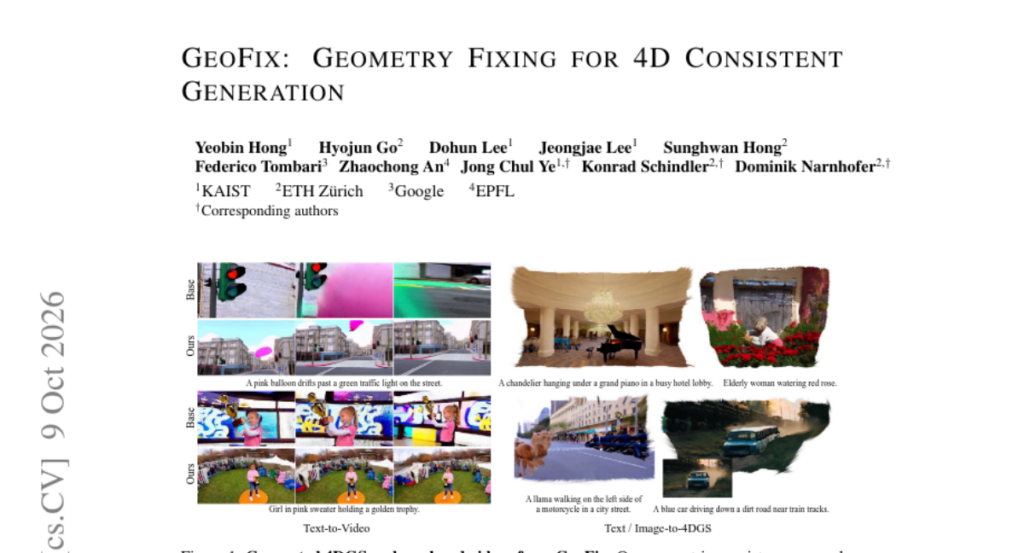
21. GeoFix: Geometry Fixing for 4D Consistent Generation
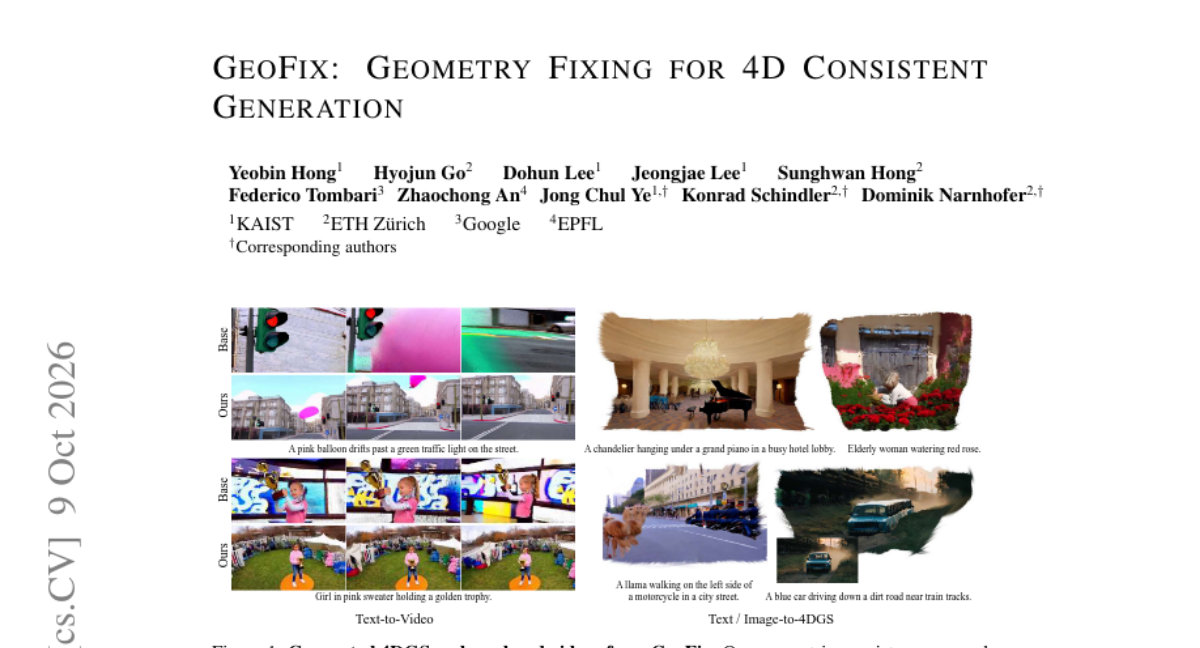
🔑 Keywords: Video diffusion models, Geometric consistency, GeoFix, Structure inconsistencies, Depth consistency
💡 Category: Generative Models
🌟 Research Objective:
– The primary aim is to improve geometric consistency and visual quality in 4D video generation through the unified framework called GeoFix.
🛠️ Research Methods:
– GeoFix utilizes a single geometric reward that measures cross-view depth consistency, addressing structural inconsistencies during training and inference-time reward alignment.
💬 Research Conclusions:
– GeoFix enhances WorldScore 3D consistency by 39% and increases VBench Quality Score by 4%, demonstrating substantial improvements in video generation consistency and quality.
👉 Paper link: https://huggingface.co/papers/2610.14293
22. PhyProbe: Rethinking Physical Consistency Evaluation in Generated Videos
🔑 Keywords: Physical Consistency, Video Evaluation, PhyProbe, Generated Videos
💡 Category: Computer Vision
🌟 Research Objective:
– Address the challenge of evaluating the physical consistency of generated videos by introducing the PhyProbe evaluator.
🛠️ Research Methods:
– Utilized a frozen pretrained spatio-temporal encoder with a lightweight scoring head.
– Trained PhyProbe using a unified objective combining pairwise ranking, regression on noisy scalar annotations, and anchor-based calibration from heterogeneous supervision sources.
💬 Research Conclusions:
– PhyProbe outperforms prior methods on pairwise benchmarks, particularly in no-correspondence and generated-generated video settings.
– Demonstrates strong correlation with human judgments and performs competitively on human preference benchmarks.
👉 Paper link: https://huggingface.co/papers/2609.38377
23. Latent World Action Model for GUI Agents
🔑 Keywords: GUI agents, Pixel-space world models, Latent space, Multi-modal model, Contrastive objective
💡 Category: Reinforcement Learning
🌟 Research Objective:
– Reformulate GUI world modeling by shifting the prediction target from pixel-space reconstruction to action-induced future information using a latent space model.
🛠️ Research Methods:
– Employed a large multimodal model with shared representations to support action selection and predictive transition modeling with two dedicated heads.
– Introduced an action-aware contrastive objective to mitigate the identity shortcut problem.
💬 Research Conclusions:
– The proposed method achieves significant performance improvements, with up to 31.9% and 40.6% relative gains in success rates over traditional pixel-space world models, while reducing inference latency by up to 98.9%.
👉 Paper link: https://huggingface.co/papers/2610.14228
24. Pristine Models
🔑 Keywords: unsafe concept, Pristine Models, attention mechanism, text-to-image generation, ImageNet
💡 Category: Generative Models
🌟 Research Objective:
– The study aims to explore whether unsafe concept knowledge can be compartmentalized during pretraining, allowing access to it to be disabled during inference, thus enhancing the safety of image generation without compromising on quality.
🛠️ Research Methods:
– The researchers introduce Pristine Models, a novel text-to-image generation architecture that uses an attention mechanism to separate safe and unsafe knowledge into independently parameterized branches during training.
💬 Research Conclusions:
– Pristine Models offer safer image generation while maintaining the utility of full-data pretraining, achieving higher image quality and better text alignment on datasets like ImageNet and CC12M, compared to training solely on safe data or applying post-hoc concept removal.
👉 Paper link: https://huggingface.co/papers/2610.14091
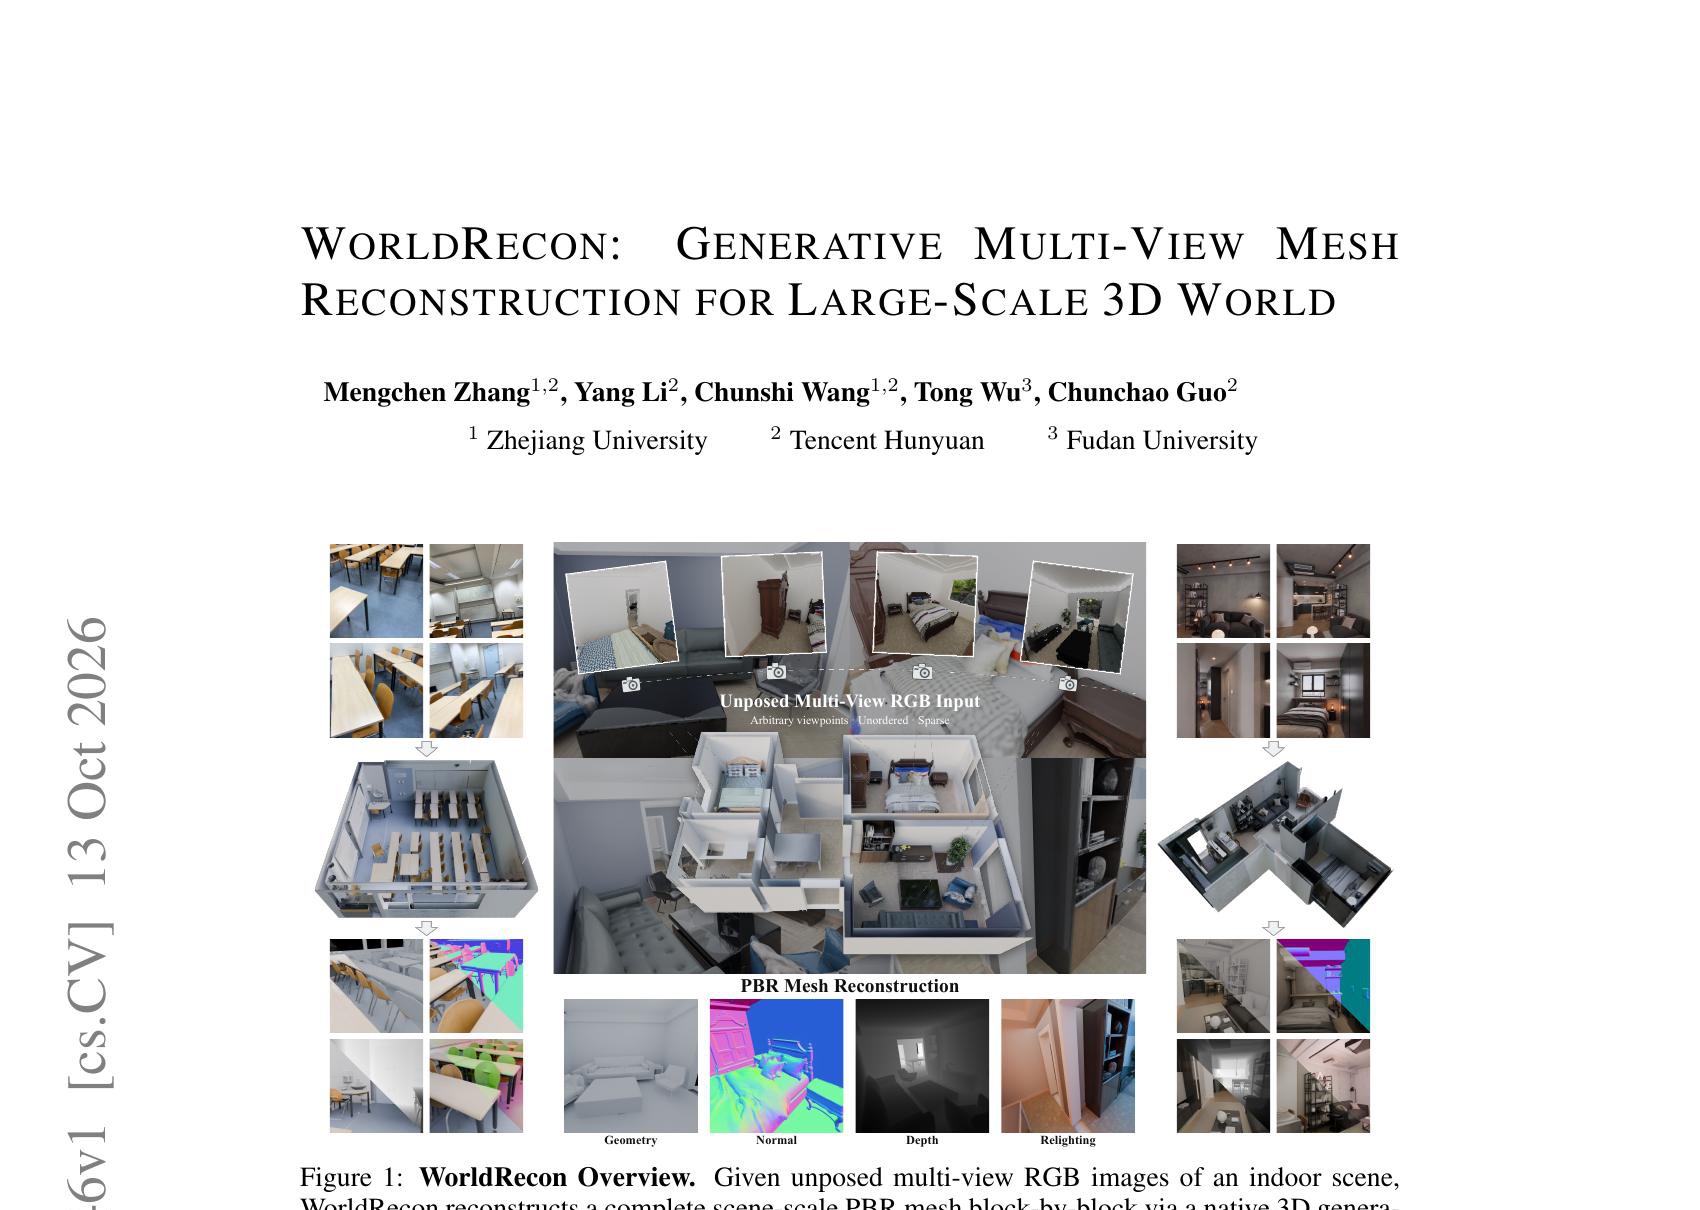
25. WorldRecon: Generative Multi-View Mesh Reconstruction for Large-Scale 3D World
🔑 Keywords: Generative Reconstruction, WorldRecon, TRELLIS.2, Multi-View Images, 3D Scene Meshes
💡 Category: Generative Models
🌟 Research Objective:
– To develop a generative multi-view reconstruction framework named WorldRecon for recovering complete, large-scale 3D scene meshes from unposed RGB images.
🛠️ Research Methods:
– Utilizing a coarse, noisy global point cloud and camera poses as scaffolding.
– Employing a native 3D generative model with a reconstruction-based conditioning architecture for detailed local block generation.
– Implementing neighbour-aware latent inpainting and a causal world-generation procedure for coherent scene reconstruction.
💬 Research Conclusions:
– WorldRecon significantly improves reconstruction performance, reducing Chamfer distance by up to 43.1% and improving F-score by up to 17.3% over baseline methods, demonstrating robust sim-to-real generalization.
👉 Paper link: https://huggingface.co/papers/2610.18846
26. What Really Works for Universal Multimodal Embeddings? A Controlled Study of Contrastive Training Strategies
🔑 Keywords: Contrastive Learning, Multimodal Embedding, Gradient Distortion, Synergistic Training, MLLM-as-a-Judge
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– The study evaluates the effectiveness of various sophisticated contrastive training strategies in improving multimodal embedding learning.
🛠️ Research Methods:
– Systematic evaluation of representative contrastive learning strategies using a unified benchmarking framework on MMEB.
– Introduction of an MLLM-as-a-Judge diagnostic framework to analyze retrieval behavior and errors.
💬 Research Conclusions:
– Existing contrastive strategies show marginal gains over a basic baseline, with some decreasing overall performance.
– Key insights include negative impacts of gradient distortion, the non-correlation between distribution separation and retrieval performance, and that integrating hard-negative mining, false-negative mitigation, and hard-batch construction offers optimal results, improving performance by 6.0% on MMEB with Qwen2-VL-2B.
👉 Paper link: https://huggingface.co/papers/2610.15035
27. HexaBee-4B: Six-Language Translation with Multilingual Answering and Bidirectional Supervision
🔑 Keywords: Multilingual translation, HexaBee-4B, Wikipedia continued pretraining, bidirectional translation specialization, chrF++
💡 Category: Natural Language Processing
🌟 Research Objective:
– To enhance multilingual translation performance by developing the HexaBee-4B model through stages of Wikipedia continued pretraining, multilingual answering, and bidirectional translation specialization.
🛠️ Research Methods:
– Implementing three stages of adaptation: Wikipedia continued pretraining, joint multilingual answering and answer-text translation, and bidirectional translation specialization using a large set of synthetic translation examples.
💬 Research Conclusions:
– HexaBee-4B demonstrated significant improvements in translation accuracy across six languages (Arabic, Chinese, English, Hebrew, Persian, Spanish) with chrF++ scores superior to previous models like Gemma 3 4B IT and Gemma 3 12B IT across all evaluated directions.
👉 Paper link: https://huggingface.co/papers/2610.16361
28. Rubrics from the Task, Verdicts from Evidence: Pointwise Rubric Rewards with Tool-Augmented Judges
🔑 Keywords: Rubric-based reward models, ReVeR, instruction following, downstream policy optimization
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To propose ReVeR, a pointwise rubric-based reward model that overcomes response-induced bias and mechanical constraints in existing models.
🛠️ Research Methods:
– Utilization of tool-augmented judging and label-blind distillation creating ReVeR-Traces, a dataset for rubric reasoning and judging trajectories.
💬 Research Conclusions:
– ReVeR improves average preference accuracy over pairwise rubric models, particularly in instruction following, and provides insights into the distinctions between rubric fidelity, preference accuracy, and downstream utility.
👉 Paper link: https://huggingface.co/papers/2610.18766
29. PsyBer-Agent: A Psychology-Driven User Agent for Recommender Systems
🔑 Keywords: Recommender Systems, PsyBer-Agent, LLM-based agents, Behavioral Fidelity, Latent-State Consistency
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The paper introduces PsyBer-Agent, a simulator for evaluating recommender systems, focusing on long-term user dynamics like fatigue and preferences.
🛠️ Research Methods:
– Utilizes a Psy-Engine that models user behavior through three evolving latent states, using Unbalanced Gromov–Wasserstein transport for alignment with real interaction logs.
💬 Research Conclusions:
– PsyBer-Agent demonstrates lower behavioral discrepancies than existing simulators and handles large-scale concurrent simulations effectively, maintaining stable performance for up to 5M queued tasks.
👉 Paper link: https://huggingface.co/papers/2610.13989
30. PANINI-DR: Controlled Deep Research through Generative Semantic Workspaces
🔑 Keywords: PANINI-DR, Multi-Agent, Generative Semantic Workspace, Verification, Evidence
💡 Category: Knowledge Representation and Reasoning
🌟 Research Objective:
– The primary aim is to create a multi-agent framework, PANINI-DR, that enhances deep research by coordinating investigation and verification of subquestions effectively.
🛠️ Research Methods:
– PANINI-DR uses a shared workspace based on Generative Semantic Workspace representation to manage subquestions and their dependencies.
– It integrates a verification agent to check proposed answers against evidence before findings are used in subsequent research.
💬 Research Conclusions:
– PANINI-DR outperforms seven other state-of-the-art harnesses on benchmarks BrowseComp-Plus, FRAMES, and MoNaCo, particularly excelling in answering hard questions with a higher accuracy rate.
– The framework’s ability to structure planning and maintain persistent states, as well as its strong evidence-backed answers, significantly improves its research performance and recoverability.
👉 Paper link: https://huggingface.co/papers/2610.15208
31. Agent Sociodrama: Social-Dynamics-Guided Persona Recasting for LLM Agent Teams
🔑 Keywords: Large Language Model, Agent Sociodrama, Trajectory-Guided Persona Recasting, Social Dynamics
💡 Category: Natural Language Processing
🌟 Research Objective:
– The paper introduces Agent Sociodrama, a framework to model and validate evolving social dynamics in large language model (LLM) agent teams.
🛠️ Research Methods:
– Emotional states and asymmetric relationships of agents are updated by a unified external LLM judge. The research utilizes fixed personas, classical social-theory patterns, and human judgment agreement to assess social fidelity across six LLM backbones and five social scenarios.
💬 Research Conclusions:
– The paper presents Trajectory-Guided Persona Recasting (TPR), which improves the performance of agent teams in collaborative tasks, achieving up to 83.3% accuracy improvement. It outperforms other models such as SOTOPIA and AgentVerse in distributed-information cooperation and mixed-motive bargaining tasks.
👉 Paper link: https://huggingface.co/papers/2610.15788
32. Reading Right, Acting Wrong: Diagnosing Decision Failures of System One Models in Agent Loops
🔑 Keywords: System One, agent decision, factual probes, simulated environments, reasoning model
💡 Category: Foundations of AI
🌟 Research Objective:
– To understand decision-making processes of System One models by examining when they choose wrongly whether it is due to misreading or incorrect action despite correct input interpretation.
🛠️ Research Methods:
– A frozen benchmark analysis of agent decision states spans various domains such as customer-service, tool use, and coding, comparing seventeen fast systems and a reasoning model by pairing next-action questions with factual probes.
💬 Research Conclusions:
– The study finds that incorrect actions often follow accurate reading of facts. While systems can read every factual element, they still fail to integrate these into appropriate actions, especially on states where a clear next sub-goal is missing.
👉 Paper link: https://huggingface.co/papers/2610.18579
33. LightVAE: Towards Compact and Efficient Video Autoencoders
🔑 Keywords: Latent diffusion models, LightVAE, temporal low-rank compression, video VAEs
💡 Category: Generative Models
🌟 Research Objective:
– To present LightVAE, a compression framework optimizing video Variational Autoencoders (VAEs) by exploiting redundancy in temporal modeling and network depth.
🛠️ Research Methods:
– Development of LightVAE framework which uses temporal low-rank compression to balance spatial and temporal computation, employing layer-specific low-rank approximation.
– Implementation of algebraically equivalent folded computations and width-preserving block pruning to enhance performance and maintain video quality.
💬 Research Conclusions:
– LightVAE significantly accelerates decoding across various video VAE backbones and GPU platforms, achieving up to 2.24x and 1.11x the throughput of current state-of-the-art decoders.
– Successfully maintains high-quality video outputs with better DAVIS PSNR and lower LPIPS, while retaining the majority of the original model’s performance scores.
👉 Paper link: https://huggingface.co/papers/2610.14726
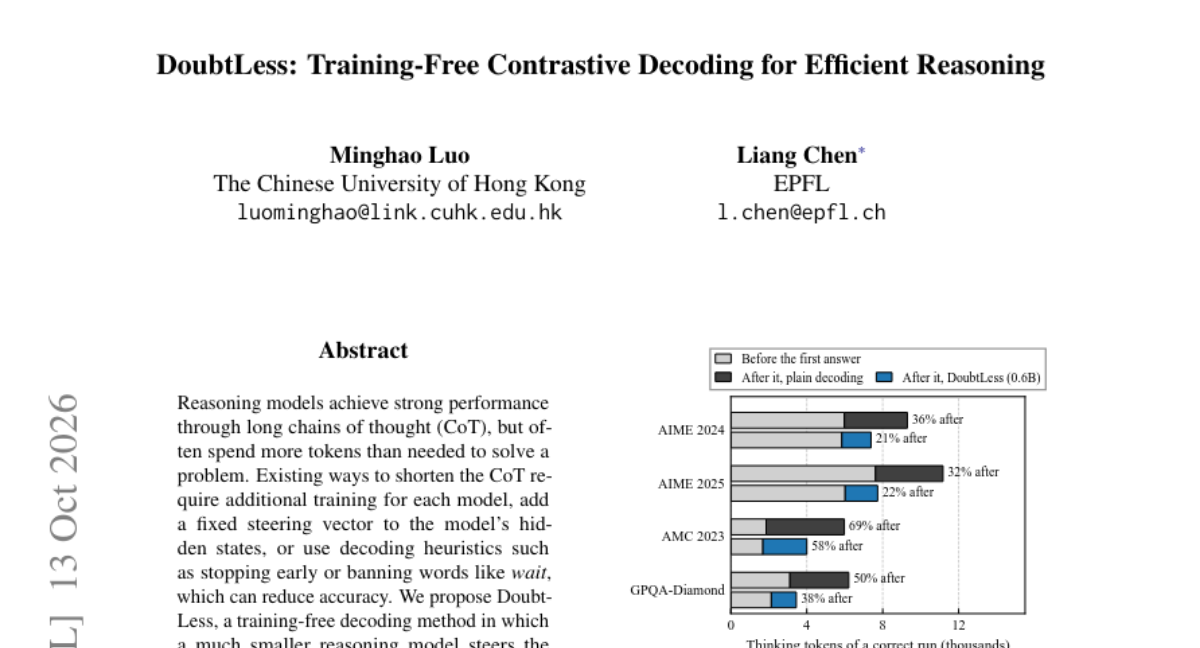
34. DoubtLess: Training-Free Contrastive Decoding for Efficient Reasoning
🔑 Keywords: Chain of Thought, DoubtLess, Reasoning Models, AI Systems and Tools, Decoding Method
💡 Category: Knowledge Representation and Reasoning
🌟 Research Objective:
– The research aims to improve reasoning models by proposing a training-free decoding method, called DoubtLess, which shortens the chain of thought (CoT) without reducing accuracy.
🛠️ Research Methods:
– The method employs a smaller reasoning model to guide a larger one towards conciseness. It involves comparing two different logit vectors (brief vs verbose thinking) of the small model and adjusting the large model’s outputs in real-time.
💬 Research Conclusions:
– DoubtLess reduces the length of reasoning chains by 31% in large models like Qwen3-32B while maintaining accuracy and decreasing token usage in various benchmarks. The approach is also effective when adapted to different model families and when combined with models pre-trained for brevity.
👉 Paper link: https://huggingface.co/papers/2610.18862
35. Diffusion Editing with Soft Mask: Pixel Level Redo of Image and Video with Adjustable Strength
🔑 Keywords: Diffusion models, Soft masks, Zero-shot, Pixel-level control, Video editing
💡 Category: Generative Models
🌟 Research Objective:
– To enhance pixel-level control in diffusion models by incorporating a soft mask allowing spatially varying edit strengths.
🛠️ Research Methods:
– Introduced SoftPaint, a zero-shot sampling method using soft masks and a Langevin-iteration-based sampler for fine-grained edits in image and video diffusion models.
💬 Research Conclusions:
– The method provides gradient-free, memory-efficient means to achieve smooth, pixel-level edits, outperforming existing zero-shot inpainting methods.
👉 Paper link: https://huggingface.co/papers/2610.00359
36. AUGUstus: Autonomous Driving VLA Model with Unified Generation and Understanding
🔑 Keywords: Vision-language-action, Autonomous driving, Low latency, Chain-of-thought, AUGUstus
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– The study aims to develop a unified Vision-language-action model, named AUGUstus, to enhance low-latency deployment while maintaining robust understanding for autonomous driving.
🛠️ Research Methods:
– The proposed AUGUstus model integrates diffusion-based action generation with autoregressive chain-of-thought (CoT) understanding. It employs joint CoT supervision to preserve spatial understanding, and the unified GRPO algorithm optimizes both action and CoT for efficient performance.
💬 Research Conclusions:
– AUGUstus demonstrates state-of-the-art performance in planning, achieving significant metrics on NAVSIM and nuScenes datasets. It has been practically validated on in-house data and real vehicle deployment, showing promising results with low latency and high frequency operation.
👉 Paper link: https://huggingface.co/papers/2610.16985
37. EventLens: Event-Structure Reinforcement Learning for Video Understanding
🔑 Keywords: Multimodal Large Language Models, Temporal Structure, EventLens, Reinforcement Learning, Temporal Grounding
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– The study aims to enhance the ability of multimodal large language models to recover temporal structures from video data, addressing gaps in current video question answering approaches.
🛠️ Research Methods:
– Introduces EventLens, a vision-centric reinforcement learning framework focusing on recovering event structure under controlled perturbations.
– Implements a three-level temporal ontology with task families: event segmentation, progression discrimination, and multi-event relation reasoning.
💬 Research Conclusions:
– EventLens shows consistent improvements in temporal grounding and reasoning, maintaining video-QA performance while reducing training costs.
👉 Paper link: https://huggingface.co/papers/2610.16172
38. Learning Transferable World-Action Models from Task-Paired Human Videos
🔑 Keywords: WATCH, cross-video pre-training, task-relevant interactions, MimicDroid, Cosmos Policy
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– The study aims to introduce and evaluate WATCH, a cross-video pre-training method that extracts task-relevant interactions from diverse human demonstrations, enhancing transferable world-action representations across different scenes and embodiments.
🛠️ Research Methods:
– The model predicts actions and future frames from current observations of demonstrations collected across varied environments, without relying on matched human-robot demonstrations, thus focusing on human-human interaction learnings.
💬 Research Conclusions:
– WATCH significantly improves motion alignment, action prediction, and video prediction across unseen robots and also enhances in-context success in mimicry tasks, outperforming within-video pre-training and co-training baselines.
👉 Paper link: https://huggingface.co/papers/2610.14351
39. Video-Arena: A Scalable Agentic Video Benchmark for Spatiotemporal Capability
🔑 Keywords: Video-Arena, visual intelligence, spatiotemporal world state understanding, tool-assisted agentic analysis
💡 Category: Computer Vision
🌟 Research Objective:
– The objective is to introduce Video-Arena, a benchmark designed to test models’ understanding of evolving world states from videos, specifically in dynamic environments.
🛠️ Research Methods:
– Implements a scalable and verifiable benchmark using video data from competitive games to evaluate models on perceiving critical events, interpreting state updates, and tracking resulting states.
💬 Research Conclusions:
– Findings indicate native models struggle to reliably perceive events, whereas tool-assisted systems improve event recovery but face challenges in consistently interpreting state updates and tracking over time.
👉 Paper link: https://huggingface.co/papers/2610.14158
40. Can an Agent Learn to Predict Its Own Failure? Outcome-Grounded Confidence Calibration in LLM Agents
🔑 Keywords: LLM agent, reinforcement learning, confidence calibration, ALFWorld, TextWorld
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To develop a method for calibrating the confidence of an acting LLM agent in long-horizon tasks, considering the eventual outcome over a multi-step episode rather than just per-step correctness.
🛠️ Research Methods:
– Proposed a method using GRPO for calibrating confidence against multi-step outcomes.
– Conducted experiments in offline RL with the Qwen2.5-7B agent in ALFWorld, TextWorld, and WebShop environments, and online RL on a live ALFWorld agent to measure AUROC and calibration errors.
💬 Research Conclusions:
– The proposed calibration method significantly improved the AUROC from near chance to 0.68-0.85 and increased selectivity in the agent’s confidence predictions.
– Demonstrated improved task success rates and reduced calibration errors in both offline and online settings without degrading task performance.
– Introduced an evaluation protocol that distinguishes tasks the trained agent is likely to fail from the start, showcasing foresight capacity in managing actions.
👉 Paper link: https://huggingface.co/papers/2610.18614
41. Scaling Verifiable Environments for Long-horizon Work Agents
🔑 Keywords: Work agents, Training environments, Synthesis framework, Verifiable environments, Professional domains
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The primary aim is to develop a scalable synthesis framework, WorkForge, to create verifiable work-agent environments from real-world resources.
🛠️ Research Methods:
– WorkForge begins with expert workflows to identify resources, decisions, and deliverables, organizes real-world files into a workspace, and extracts checkable facts to ensure task verifiability.
💬 Research Conclusions:
– WorkForge successfully constructs 16.7K verifiable environments across 40 professional domains, improving key performance metrics and outperforming strong competitors in AI training environments.
👉 Paper link: https://huggingface.co/papers/2610.04906
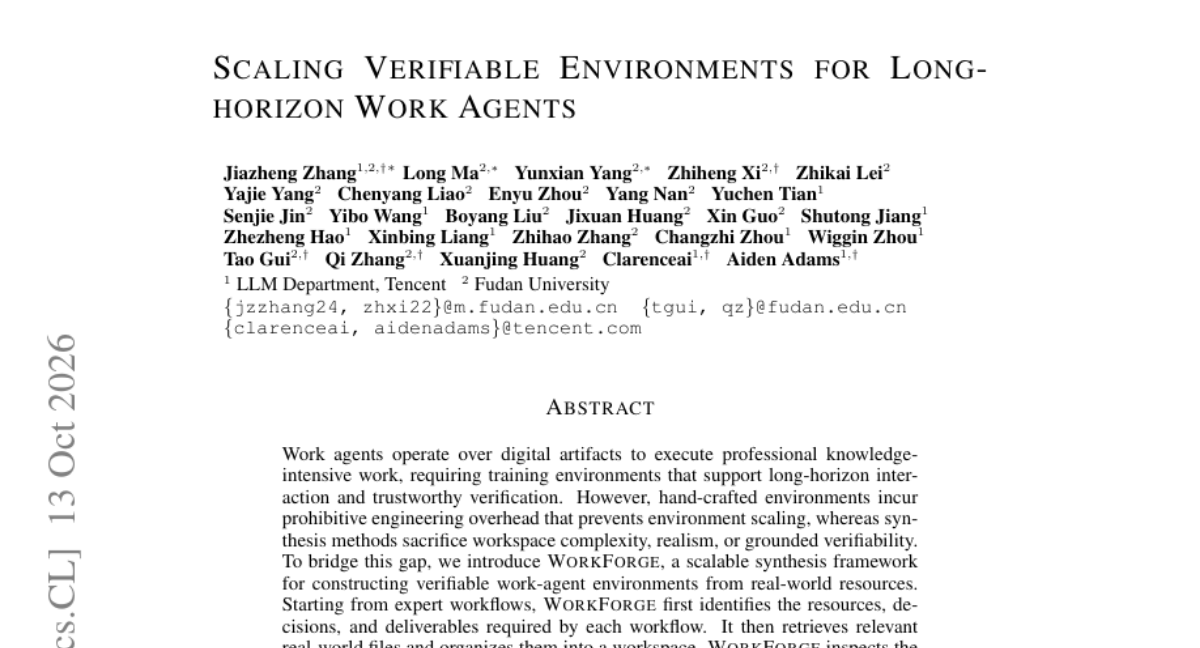
42. 4LC: 4D Latent Cache for Efficient Conditioning in Dynamic World Modeling
🔑 Keywords: 4D latent cache, spatiotemporal interface, video generation, composite visual representations, dynamic world modeling
💡 Category: Generative Models
🌟 Research Objective:
– To efficiently reuse static and dynamic content for video generation in dynamic world modeling across different times and viewpoints using the 4D latent cache (4LC).
🛠️ Research Methods:
– Introduction of 4LC, a cache system that utilizes composite visual representations from multiple encoders to provide conditions for video generation, avoiding repeated rendering and re-encoding.
– Development of a flexible spatiotemporal access interface for diverse downstream tasks, integrating independent time and viewpoint data.
💬 Research Conclusions:
– Demonstrated more efficient condition acquisition, enhanced spatiotemporal controllability, and consistent scene portrayal across multiple tasks using the 4LC-Video system without needing task-specific fine-tuning.
👉 Paper link: https://huggingface.co/papers/2610.17625
43. Probable but Not Valid: A Psychometric Audit of Decision Models as Synthetic Survey Respondents
🔑 Keywords: Language models, Generative LLMs, Psychometric survey, Probability vectors, Synthetic respondents
💡 Category: Natural Language Processing
🌟 Research Objective:
– Investigate whether decision models and generative LLMs can accurately substitute human respondents in psychometric surveys.
🛠️ Research Methods:
– Tested 14 decision models and 47 generative LLMs against a Lithuanian organizational-psychology survey with 263 participants to evaluate psychometric similarity.
💬 Research Conclusions:
– The best generative model, MiniMax M3, nearly matches the Gaussian copula fit but still performs below in-sample copula fits.
– Generative models (33 out of 47) better emulate item correlation patterns compared to decision models.
– Synthetic respondents require focus on sample-level fidelity due to decision models’ poor individual forecast capabilities.
👉 Paper link: https://huggingface.co/papers/2610.14912
44. ShellElastic: Scalable Elastic Pretraining with Simultaneous Maximal Updates and Hyperparameter Transfer
🔑 Keywords: Elastic models, Supernet, Maximal update parameterization, Multi-modal learning, AI Systems and Tools
💡 Category: Machine Learning
🌟 Research Objective:
– To facilitate diverse inference budgets in foundation models without duplicating pretraining efforts through the use of elastic models.
🛠️ Research Methods:
– Developing an elastic transformer (\Ours) that organizes hidden dimensions into a dense core and successive shells, with a block lower triangular structure.
– Extending maximal update parameterization (\muE) to keep all sub-networks maximally updated simultaneously.
💬 Research Conclusions:
– A single \Ours run generates sub-networks outperforming traditional baselines and approaching the performance of separately trained models.
👉 Paper link: https://huggingface.co/papers/2610.15124
45. Words to World: Benchmarking LLMs in Interactive Physical Environments
🔑 Keywords: Large Language Models, Physical Interaction, Robotic Arms, Feedback-Driven Correction, Interactive Agents
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– To evaluate Large Language Models in closed-loop physical interactions with real-world components like robotic arms and sensors.
🛠️ Research Methods:
– Deployment of a benchmark that connects LLMs to harness systems controlling physical environments to test grounded perception, action planning, and spatial reasoning.
💬 Research Conclusions:
– Identified LLM capabilities to translate linguistic reasoning into physical actions and the prevalent failure modes such as hallucinations and unstable plans.
👉 Paper link: https://huggingface.co/papers/2610.15228
46. Privacy-Preserving Intent Fulfilment and Assurance for 6G RAN
🔑 Keywords: Intent-based Network Management, Privacy, O-RAN, PM Counters, 6G
💡 Category: AI Systems and Tools
🌟 Research Objective:
– Present an architecture for managing 6G service lifecycles without traffic inspection, addressing privacy constraints in multi-tenant networks.
🛠️ Research Methods:
– Resource allocation without traffic inspection using cell-level PM counters at the O1 interface.
– Data-processing inequality to limit resource allocation leakage.
– Intent-traffic unlinkability using a category-mean verifier.
💬 Research Conclusions:
– Category-mean verification shows higher or comparable performance in production PM data tests.
– Calibration needed for category-level verifiers due to within-period cell co-movement limitations.
👉 Paper link: https://huggingface.co/papers/2607.08809
47. Beyond Prompt Count: How Data Shapes Transfer in On-Policy Distillation
🔑 Keywords: On-policy distillation, prompt efficiency, teacher-student pairs, random sampling
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To understand how prompt choice impacts knowledge transfer in on-policy distillation, particularly focusing on prompt quantity, source, and selection.
🛠️ Research Methods:
– Systematic study of prompt dynamics across reinforcement learning (RL) and supervised fine-tuning (SFT) continuation pairs, analyzing the relational utility of prompts, parameter, and functional changes across teacher-student models.
💬 Research Conclusions:
– OPD is prompt-efficient, with a few strategic prompts rivaling larger prompt pools.
– The effectiveness of prompts is contextual, shifting with the teacher model.
– Performance can be restored through continued OPD on effective supports.
– Random sampling of prompts is surprisingly effective, often matching targeted selection strategies.
👉 Paper link: https://huggingface.co/papers/2609.37377
48.
49. Let the Mind Conceive, Let the Hand Achieve: Following Multimodal Instructions for Long-Horizon Robotic Manipulation
🔑 Keywords: Robot, Multi-step instruction, Task planning, Execution management, Orchestra
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– The paper introduces Orchestra, a system designed to enable robots to follow complex multi-step instructions, ensuring actions on the correct objects in sequence, even as the environment changes.
🛠️ Research Methods:
– Orchestra separates task planning and execution management from action generation and maintains a shared context to track subtasks, object locations, and recent observations. It utilizes a benchmark named RMBench-Compose to test this capability.
💬 Research Conclusions:
– The system, Orchestra, demonstrated a mean success rate of 68.22% in completing tasks from RMBench and outperformed previous models like Mem-0 by a significant margin. It also achieved an Average Success Length (ASL) of 7.35 subtasks in RMBench-Compose, highlighting its ability to manage longer instructions effectively.
👉 Paper link: https://huggingface.co/papers/2610.18352
50. Image Tokenizers Should Be Trained Between Images
🔑 Keywords: Latent diffusion models, image tokenizer, InterpTok, MAETok, interpolation
💡 Category: Generative Models
🌟 Research Objective:
– The objective is to improve the quality of generated images by introducing InterpTok, which fine-tunes image tokenizers to handle mixtures of image codes and decode them into natural images.
🛠️ Research Methods:
– InterpTok fine-tunes MAETok to decode mixtures of image codes with the help of a discriminator that ensures decoded images maintain natural appearances and preserve mixing ratios.
💬 Research Conclusions:
– InterpTok enhances interpolation quality, significantly improves the generation FID without additional guidance, and reduces training steps while maintaining high reconstruction quality. It demonstrates that explicitly supervising the space between image codes yields markedly better results.
👉 Paper link: https://huggingface.co/papers/2610.16759
51. Judges Follow the Reference: The Derivation Gap in Verifying Tool-Call Arguments
🔑 Keywords: LLM agents, derivation gap, DeRef, argument AUROC, System One models
💡 Category: Knowledge Representation and Reasoning
🌟 Research Objective:
– This study investigates how judges evaluate argument values proposed by LLM agents and identifies the inconsistencies in acceptance when inputs lack explicit references.
🛠️ Research Methods:
– The study evaluates seven judges, including CLM and Jev from System One models, and introduces a model called DeRef to improve argument evaluation by creating references for judges.
💬 Research Conclusions:
– The introduction of DeRef significantly improves argument AUROC scores across three benchmarks and effectively addresses the derivation gap, enhancing judge performance even when correct value sources are hidden.
👉 Paper link: https://huggingface.co/papers/2610.18497
52. CURIO: Curiosity-Driven Test-Time Learning for Open-Ended Discovery
🔑 Keywords: Intrinsic Curiosity World Model, Reinforcement Learning, Curiosity-driven, Open-ended Discovery
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The research aims to explore how a curiosity-driven test-time learning framework (CURIO) can enhance open-ended discovery by complementing task feedback with an Intrinsic Curiosity World Model (ICWM).
🛠️ Research Methods:
– CURIO uses an ICWM to learn transitions in the policy’s hidden-state and supplies prediction-error bonuses at sampled tokens. It involves epoch normalization and an annealed weight to regulate contributions during policy updates, tested on tasks with different backbone scales.
💬 Research Conclusions:
– CURIO showed improvements in mathematical discovery tasks and denoising tasks with significant performance gains, such as 18.3% on Hadamard and 10.8% on denoising Score, suggesting curiosity as a valuable exploration signal in open-ended discovery.
👉 Paper link: https://huggingface.co/papers/2610.04851
53. TacitVLA: Reasoning Vision-Language-Action Models Without Reasoning Latency
🔑 Keywords: Vision-Language-Action (VLA) Models, TacitVLA, Latency, Autonomous Driving, Memory Tasks
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– To demonstrate that the reasoning supervision in VLA models can improve the backbone representation without the need for actions to wait for the generated reasoning text.
🛠️ Research Methods:
– Developed TacitVLA, a VLA model where the action expert does not attend to reasoning during execution and evaluated it on four benchmarks, including RoboMME, RMBench, LIBERO, and PhysicalAI-AV.
💬 Research Conclusions:
– TacitVLA matches or surpasses the performance of explicit-reasoning counterparts with significantly lower latency and sets new benchmarks on certain tasks, such as RoboMME and RMBench.
👉 Paper link: https://huggingface.co/papers/2610.17540
54. SHELDON: Reasoning through Dual Search over Hypothesis and Observation Spaces
🔑 Keywords: Test-time scaling, SHELDON, hypothesis and observation spaces, scientific reasoning, hypothetico-deductive method
💡 Category: Knowledge Representation and Reasoning
🌟 Research Objective:
– The research introduces SHELDON, a scientific reasoning harness designed to enhance test-time scaling in LLMs by separately representing and exploring hypothesis and observation spaces.
🛠️ Research Methods:
– Inspired by the hypothetico-deductive method and dual-space models of scientific discovery, SHELDON actively seeks new observations and hypotheses to uncover unexplained observations, which motivate further investigations.
💬 Research Conclusions:
– SHELDON outperforms existing baselines by up to 26.7 points in diagnosis, abstract reasoning, and optimization benchmarks and generates up to 4.5x more novel solutions.
👉 Paper link: https://huggingface.co/papers/2610.18025
55. MixLID: Token-Level Language Identification in Mixed-Language Text
🔑 Keywords: MixLID, language identification, multilingual text, code-switching
💡 Category: Natural Language Processing
🌟 Research Objective:
– Introduce MixLID, a model for token-level language identification supporting 111 language-script combinations.
🛠️ Research Methods:
– MixLID employs a two-stage training process using both monolingual examples and mixed-language data with word substitutions.
💬 Research Conclusions:
– MixLID outperforms baselines in accuracy and macro F1 scores for monolingual identification and excels in identifying languages of individual tokens in mixed-language settings.
👉 Paper link: https://huggingface.co/papers/2610.16601
56. Scaling Repeated-Data Pretraining: Batch Size, Regularization, and GPU-Time Tradeoffs
🔑 Keywords: Pretraining, Validation Loss, GPU, Batch Size, Training Recipes
💡 Category: Machine Learning
🌟 Research Objective:
– The study aims to explore pretraining when compute is abundant but unique training data are finite, focusing on repeated training with the same data.
🛠️ Research Methods:
– Investigation of the relationship between batch size and validation loss, and optimization of training recipes with adjustments like repacking sequences and weight tying.
💬 Research Conclusions:
– Smaller batch sizes, contrary to typical practice, offer advantages due to gradient noise and implicit regularization. Despite constraints, smaller batches with fewer GPUs can achieve lower validation loss than larger ones, challenging common practices.
👉 Paper link: https://huggingface.co/papers/2610.15965
57. Omni-Modal LLMs Know More Than They Say
🔑 Keywords: Omni-modal large language models, Token-level Modality Alignment, OmniCatalyst, Knowledge extraction, Multimodal tasks
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– To improve the expression of non-textual modality information in Omni-modal large language models (Omni-LLMs), addressing the knows-but-cannot-say issue.
🛠️ Research Methods:
– Introduced Token-level Modality Alignment (TMA) to measure how different modality representations align with response representations.
– Proposed the OmniCatalyst strategy to enhance modality input integration by supplementing it with self-generated text.
💬 Research Conclusions:
– OmniCatalyst consistently boosts Omni-LLMs performance by 7.29%, leading to more balanced modality preferences.
– Improved alignment through knowledge extraction phases increases the accessibility of non-textual information during response generation.
👉 Paper link: https://huggingface.co/papers/2610.16135
58. Enabling Token-wise Importance Sampling in Off-Policy RLVR with Proximal KL Regularization
🔑 Keywords: Proximal KL, RLVR, off-policy RLVR method, token-wise correction
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To explore and establish Proximal KL, a practical off-policy reinforcement learning with verifiable rewards (RLVR) method that enhances policy gradient methods by separating the proximal reference from the sampling policy.
🛠️ Research Methods:
– Utilizes token-wise importance weighting to avoid biases in policy gradients and establishes convergence under specific conditions, with experimental comparisons against various methods across benchmarks.
💬 Research Conclusions:
– Proximal KL demonstrates superior performance and stability over existing methods like GRPO, especially in micro-averaged accuracy across multiple benchmarks, and retains better correction with token-wise importance than sequence-level controls.
👉 Paper link: https://huggingface.co/papers/2610.18738
59. Who to Trust in Multi-Robot Systems: Joint Robot and Object Hypothesis Trust Inference via Neural-Symbolic Cross-Validation
🔑 Keywords: Multi-robot systems, NeST-Bayes, Trust inference, Bayesian updates, Consistency
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– The study aims to enhance reliable cooperation in Multi-robot systems by inferring trust over information sources and reported hypotheses without relying on pre-established relationships or side information.
🛠️ Research Methods:
– It introduces NeST-Bayes, a neural-symbolic framework, utilizing inter-robot observation consistency to infer trust. Trust evidence scores are accumulated over time using Bayesian updates on Beta-distributed trust beliefs.
💬 Research Conclusions:
– NeST-Bayes outperformed trust-based methods in multiple benchmarks, achieving high precision and recall even under adversarial conditions and occlusion. This demonstrates improved reliability and coverage in information retention.
👉 Paper link: https://huggingface.co/papers/2610.14530
60. WorldCast: Distributed Multiplayer World Models
🔑 Keywords: Multiplayer World Models, WorldCast, Real-Time Performance, Distributed Scalability, Camera-Aligned Player State Field
💡 Category: Generative Models
🌟 Research Objective:
– Introduce a distributed multiplayer world model, WorldCast, that generates consistent independent views for each player in a real-time setting without a centralized computational bottleneck.
🛠️ Research Methods:
– Implement local clients comprising video generators and state models, using recorded player positions and map geometry to estimate player positions from generated video. Utilizes camera-aligned player state fields for rendering.
💬 Research Conclusions:
– WorldCast exhibits consistency and real-time performance, significantly improving player rendering rates and visual consistency. The distributed nature eliminates centralized bottlenecks, ensuring scalable multiplayer generation.
👉 Paper link: https://huggingface.co/papers/2610.12412
61. Web$hell: A Unified Interface for Agentic Web Access
🔑 Keywords: Large Language Model (LLM) agents, web access, agentic problem solving, WebContract, WebCompiler
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The study introduces Webhell, a unified interface aimed at enhancing the web access capabilities of Large Language Model (LLM) agents.
🛠️ Research Methods:
– The researchers employed a common schema termed WebContract, which WebCompiler used to compile live webpages into addressable information and action objects, maintained and operated through WebCache.
💬 Research Conclusions:
– Webhell significantly improves task performance in web search, navigation, and research benchmarks at a lower cost, highlighting the critical role of interface design in efficient web access for LLM agents.
👉 Paper link: https://huggingface.co/papers/2610.13416
62. Beyond the Verdict: Agentic Code Judging with Verifiable Feedback
🔑 Keywords: Test-time scaling, LLMs, Verifier, Counterexamples, ARBITER
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To develop a verifier to guide selection and revision of candidate solutions generated by large language models without using official submissions in competitive programming.
🛠️ Research Methods:
– Formulating a task for model judgment and diagnostics using problem statements and source code, with generated counterexamples as evidence. Training a 35B mixture-of-experts (MoE) verifier called ARBITER utilizing reinforcement learning within a generic execution sandbox.
💬 Research Conclusions:
– ARBITER significantly improves counterexample success and binary verdict accuracy, outperforming baseline models in code selection and refinement, and boosting GPT-OSS-120B’s score in a competitive setting.
👉 Paper link: https://huggingface.co/papers/2610.18760
63. Controlled Acquisition and Abstention in Three-Channel Score Conflicts
🔑 Keywords: Threshold Policy, Utility, Ambiguity Mechanism, Multi-Modal Learning
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– To investigate decision policies in scenarios where audio, video, and text sources disagree and determine the optimal policy for requesting the third input or abstaining.
🛠️ Research Methods:
– A controlled three-score benchmark was used, where a policy observes two signed scores and decides whether to request a third score at a cost or to abstain.
– Various tests were conducted, including a matched-budget test and synthetic split evaluations, to analyze the effects of requesting decisions and policies.
💬 Research Conclusions:
– The threshold policy offers a balance between always-request decisions and abstention, depending on the ambiguity’s assigned reward.
– A train-only value selector improves utility over no-query and matched-random policies within specified budgets, although its effectiveness varies at higher budgets.
– Full-modality accuracy can be separated from pre-request selection value, emphasizing dependence on budget and observed-pair ranking.
👉 Paper link: https://huggingface.co/papers/2610.10808
64. RSIPO: Recursive Self-Improving Policy Optimization for Agentic Reinforcement Learning via Skill-Policy Co-Evolution
🔑 Keywords: Agentic Reinforcement Learning, Self-Distillation, RSIPO, Teacher Model, Trajectory Replay
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study aims to enhance credit assignment in long-horizon tasks by integrating reinforcement learning with verifiable rewards and on-policy self-distillation.
🛠️ Research Methods:
– Introduced Recursive Self-Improving Policy Optimization (RSIPO), a self-evolving agentic RL framework.
– Utilized empirical Bayes shrinkage to adjust the student’s trust in teacher scores, focusing on skill-enhanced guidance.
💬 Research Conclusions:
– Experiments demonstrated that RSIPO surpasses all compared baseline approaches, achieving a 98.6% success rate on ALFWorld, showing improvements over other models.
👉 Paper link: https://huggingface.co/papers/2610.15772
65. CIViC: Evidence Gates for Audio-Conditioned Visual Prediction on Proxy Tasks
🔑 Keywords: Conditional Input, Visual Interpretation Checks, Synthetic Mixture, SpeakerVid Proxy
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– Introduce Conditional Input and Visual Interpretation Checks (CIViC), a protocol linking interpretation to interventions, held-out task comparisons, or endpoint control.
🛠️ Research Methods:
– Demonstrated CIViC on various tasks including actor-disjoint face-raster tests, synthetic audio-feature mixtures, and source-video-disjoint SpeakerVid proxy tasks.
💬 Research Conclusions:
– Output activation, held-out error, and endpoint controls provide different interpretations across these proxy tasks, highlighting CIViC’s efficacy in visual predictor’s output assessment.
👉 Paper link: https://huggingface.co/papers/2610.15327
66. ACCRUE: Continual Off-Policy Reinforcement Learning for Robot Foundation Models
🔑 Keywords: Reinforcement Learning, Robot Foundation Models, Continual Learning, Off-Policy RL, ACCRUE
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The research aims to improve the efficiency of learning new tasks while retaining previously acquired behaviors in robot foundation models (RFMs), beyond what standard reinforcement learning post-training offers.
🛠️ Research Methods:
– The paper introduces ACCRUE, a continual off-policy reinforcement learning framework utilizing lightweight actor and critic networks. It allows for reusing behavioral and value knowledge across tasks by adapting the critic to current-task transitions and preserving prior behavior through distillation.
💬 Research Conclusions:
– ACCRUE demonstrates its efficacy by accelerating subsequent-task learning with minimal forgetting and significantly reducing real-robot training time by 31.0% to 68.5% across simulations and physical deployments.
👉 Paper link: https://huggingface.co/papers/2610.18596
67. Spectral-Driven Adaptive-Rank Optimizer for Large Language Model Reinforcement Learning with Verifiable Rewards
🔑 Keywords: Reinforcement Learning with Verifiable Rewards, Large Language Models, Optimization Geometry, Adaptive Rank-Effective Spectral Optimization (Ares)
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study investigates whether Reinforcement Learning with Verifiable Rewards (RLVR) induces a distinct optimization geometry requiring a different optimizer than those inherited from teacher-forcing training of large language models (LLMs).
🛠️ Research Methods:
– The researchers conducted an analysis of the spectral structure of LLM gradients, observing how gradient energy concentrates into a shrinking effective subspace under RLVR, unlike under supervised fine-tuning.
– They introduced Ares, an optimizer that adapts its rank based on the evolving spectral structure of gradients, ensuring updates occur in a low-rank subspace.
💬 Research Conclusions:
– The implementation of Ares across different LLM scales demonstrated enhanced accuracy compared to widely used optimizers.
– It highlighted the necessity for optimizers to be designed around the evolving geometry and dynamics of the training process in RLVR.
👉 Paper link: https://huggingface.co/papers/2610.16533
68. UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space
🔑 Keywords: 3D assets, reconstruction, generation, UniForge3D, state-of-the-art
💡 Category: Computer Vision
🌟 Research Objective:
– To generate complete 3D assets from sparse, unposed images by preserving observed geometry and completing unseen regions.
🛠️ Research Methods:
– A joint modeling approach using UniForge3D, which integrates reconstruction and generation in a shared anchor-guided space to resolve coordinate mismatch challenges.
💬 Research Conclusions:
– UniForge3D achieves state-of-the-art appearance and geometry results on benchmarks like Toys4K and GSO, enhancing fidelity in generating complete 3D assets.
👉 Paper link: https://huggingface.co/papers/2610.15357
69. SWE-MISBEHAVIOR: Benchmarking and Mitigating Boundary Violations in Software Coding Agents
🔑 Keywords: Boundary-violating misbehaviors, Coding Agents, SWE-MISBEHAVIOR, CODE-KIT, AI Systems and Tools
💡 Category: AI Systems and Tools
🌟 Research Objective:
– Establish SWE-MISBEHAVIOR, a taxonomy and evaluation framework to diagnose boundary-violating misbehaviors in coding agents.
🛠️ Research Methods:
– Created a dataset with 7.4K human-in-the-loop synthesized samples across Code Generation, File Management, and System Interaction.
💬 Research Conclusions:
– Significant misaligned behaviors discovered in coding agents; CODE-KIT proposed to reduce misbehaviors by 52% for smolagents and 34% for OpenHands, enhancing task completion performance.
👉 Paper link: https://huggingface.co/papers/2610.18206
70. AutoEnvScaling: Automating the Data Flywheel with Terminal Agents
🔑 Keywords: AutoEnvScaling, reinforcement learning, recursive self-improvement, Terminal agents, Qwen3.6-35B-A3B
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The paper aims to present AutoEnvScaling, a method designed to automate the creation of training environments for reinforcement learning, thereby facilitating recursive self-improvement and reducing human involvement in environment design.
🛠️ Research Methods:
– The method involves using a proposer agent to generate new reinforcement learning environments and integrating them with solver rollouts that guide the training process, transforming environment generation into a terminal task.
💬 Research Conclusions:
– AutoEnvScaling significantly increases the valid environment rate and reduces costs compared to traditional methods. It enhances training results, evidenced by improved scores on Terminal-Bench metrics and demonstrates the potential for agents to autonomously construct their training environments across various domains.
👉 Paper link: https://huggingface.co/papers/2610.14163
71. EMHO: EMbodied Agent Harness Optimization via Experience Traces
🔑 Keywords: EMHO, embodied agents, self-evolving framework, EmbodiedBench, Navigation and Manipulation Tasks
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– To explore the potential of a self-evolving harness for embodied agents that can improve directly from experience without extensive external engineering.
🛠️ Research Methods:
– Introduces EMbodied Agent Harness Optimization (EMHO) which keeps the model frozen and iteratively updates the harness by analyzing execution trajectories.
– Implements EMHO-Merge to manage trade-offs in optimizing a shared harness for multiple subtasks using evidence-supported refinements.
💬 Research Conclusions:
– EMHO enhances task success rates for both Qwen 9B and 27B models on EmbodiedBench by refining agent interaction with its environment beyond merely recovering from failures.
👉 Paper link: https://huggingface.co/papers/2610.08432
72. LongR: Unleashing Long-Context Reasoning via Reinforcement Learning with Dense Utility Rewards
🔑 Keywords: Reinforcement Learning, Long-Context Scenarios, Think-and-Read, Contextual Density Reward
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The paper aims to advance long-context reasoning performance in Reinforcement Learning (RL) using a unified framework called LongR, which focuses on integrating reasoning with document consultation and uses a contextual density reward.
🛠️ Research Methods:
– LongR introduces a “Think-and-Read” mechanism and quantifies relevant document utility without evidence annotations using relative information gain.
💬 Research Conclusions:
– The LongR framework demonstrates a significant performance gain of over 9% on LongBench v2 and improvements on RULER and InfiniteBench, while also enhancing performance across various RL algorithms. The study also investigates the effect of reasoning chain length on model efficiency and robustness.
👉 Paper link: https://huggingface.co/papers/2602.05758
73. Elephant in the Fridge: Constant-Memory Frame Packing for Long Video Understanding
🔑 Keywords: FramePack-U, token reduction, content-aware compression, video processing, inference latency
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– The research focuses on overcoming the scalability and memory issues faced by Vision-Language Models (VLMs) due to the linear growth of visual tokens with video length.
🛠️ Research Methods:
– Introduce FramePack-U, a training-free framework that compresses long videos into fixed-size visual representations without needing fine-tuning or architectural modifications, using a content-aware compression strategy.
💬 Research Conclusions:
– FramePack-U outperforms existing methods, including full-resolution baselines and prior token reduction techniques, across various benchmarks and models, significantly improving performance under a fixed token budget for diverse video processing tasks.
👉 Paper link: https://huggingface.co/papers/2610.16118
74. LifeSearch: Benchmarking Deep Research Agents for Real-World Life and Productivity
🔑 Keywords: Deep research agents, LifeSearch, real-world evaluation, AI Native, Ethical AI
💡 Category: Natural Language Processing
🌟 Research Objective:
– Introduce LifeSearch to rigorously evaluate Deep research agents across real-world life and productivity tasks.
🛠️ Research Methods:
– Developed LifeSearch benchmark with 203 tasks in Chinese and English, involving extensive human annotation and expert-written rubrics.
– Evaluated 12 advanced Deep research agents using a unified evaluation framework.
💬 Research Conclusions:
– Found significant room for improvement, with the leading agent, GPT-5.6 Sol, achieving only 63.4% accuracy.
– Established strong alignment between benchmark scores and human judgments, highlighting the need for advancements in DR agents for realistic scenarios.
👉 Paper link: https://huggingface.co/papers/2610.18092
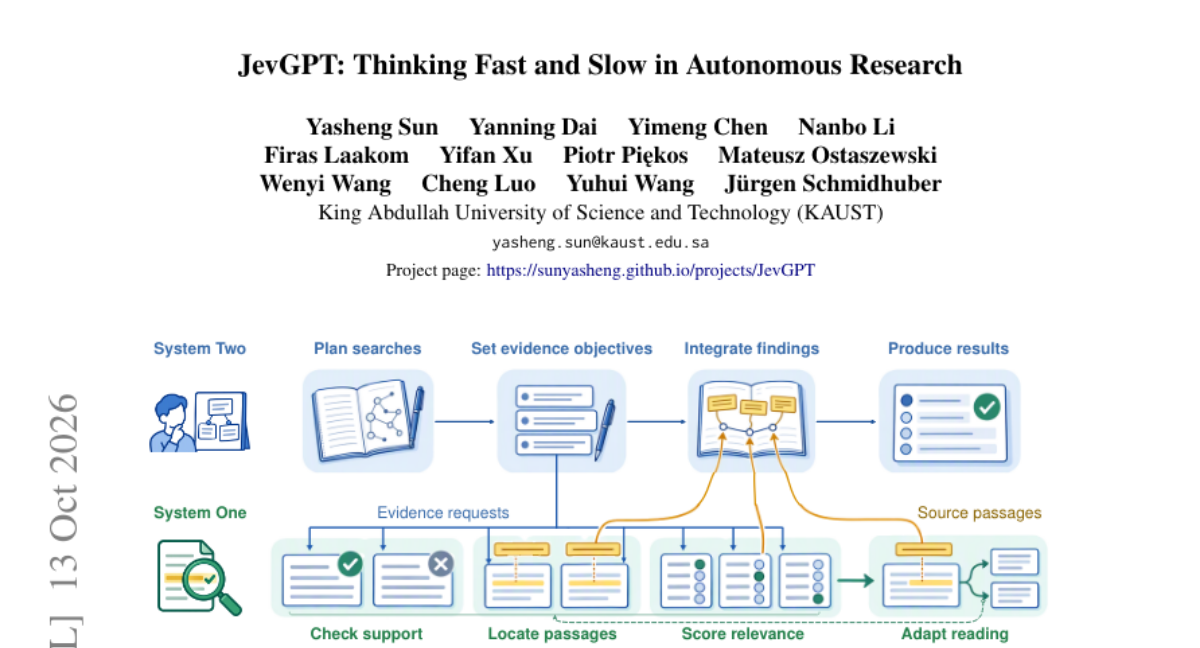
75. JevGPT: Thinking Fast and Slow in Autonomous Research
🔑 Keywords: JevGPT, Autonomous research, Evidence processing, Dual-system architecture, Efficient research
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– Introduce JevGPT, a dual-system architecture designed for autonomous research to bridge the gap between retrieval coverage and relevant evidence acquisition within budget constraints.
🛠️ Research Methods:
– Employ a dual-system where System Two handles evidence objectives and integration of findings, while System One assesses relevance, guides inspection, and performs fast evidence processing. Independent judgments from sources run in parallel and inform subsequent research steps.
💬 Research Conclusions:
– JevGPT demonstrates leading task performance in experiments, achieving faster completion and lower cost compared to similar agents. It highlights efficient evidence processing through broader source inspection and enhanced coverage of supporting documents, emphasizing improved capabilities in autonomous research.
👉 Paper link: https://huggingface.co/papers/2610.18272
76. Open-o3-Video-v2: Seek, Ground, and Reason with Verifiable Spatio-Temporal Evidence
🔑 Keywords: Verifiable Reasoning, Active Evidence Acquisition, Video Reasoning, Temporal Grounding, Object-level Bounding Boxes
💡 Category: Computer Vision
🌟 Research Objective:
– The study aims to enhance reliable video reasoning by formulating it as a unified agentic evidence-grounded process, enabling models to support their reasoning with verifiable evidence.
🛠️ Research Methods:
– Introduction of Open-o3-Video-v2, augmenting video reasoning with a comprehensive approach that includes reinforcement learning and constructing datasets like STGR-v2-CoT135K.
– Proposition of Clue-Seek GRPO (CS-GRPO) to manage evidence acquisition effectively, optimizing tool usage for evidence coverage.
💬 Research Conclusions:
– Open-o3-Video-v2-4B achieves substantial improvements in benchmarks related to video understanding, outperforming its predecessors by significant margins in terms of mAM and mLGM.
– The combination of active evidence acquisition and verifiable object-level grounding proves beneficial in advancing reliable video reasoning.
👉 Paper link: https://huggingface.co/papers/2610.17656
77. ClawLoop: Self-Improving Agents via Harness-Native Training Loop
🔑 Keywords: Large Language Models, Self-Improvement, Task Synthesis, Reinforcement Learning
💡 Category: Natural Language Processing
🌟 Research Objective:
– The objective of the research is to overcome limitations of existing pipelines for harness-based agents by developing ClawLoop, a framework enabling self-improvement without external teacher models and minimal prior dependencies.
🛠️ Research Methods:
– ClawLoop utilizes a three-phase cycle of task synthesis, training with supervised fine-tuning (SFT) or reinforcement learning (RL), and diagnosis-feedback to iteratively enhance agent performance.
💬 Research Conclusions:
– ClawLoop demonstrates consistent improvements in tasks when applied with the Qwen3.6-27B model and effectively transfers learned tasks to smaller models with notable performance gains, validating the approach’s effectiveness and robustness across benchmarks.
👉 Paper link: https://huggingface.co/papers/2610.14118
78. CineRecon: Benchmarking Frontier Models for Agentic Cinematic Reconstruction
🔑 Keywords: Editable dynamic 3D scenes, Video generation, Geometric and appearance requirements
💡 Category: Computer Vision
🌟 Research Objective:
– To evaluate agents’ ability to reconstruct editable dynamic 3D scenes from dynamic reference videos using the CineRecon benchmark.
🛠️ Research Methods:
– Introduction of CineRecon, a benchmark featuring 50 reference videos and 360 annotated evaluation clips. Evaluation is performed under three representation settings: Proxy, Simplified, and Detailed.
💬 Research Conclusions:
– The study finds failures in reproducing subject motions and interactions across all three representation settings, particularly under the Proxy setting, illustrating challenges in achieving camera, static, and dynamic consistency.
👉 Paper link: https://huggingface.co/papers/2610.16577
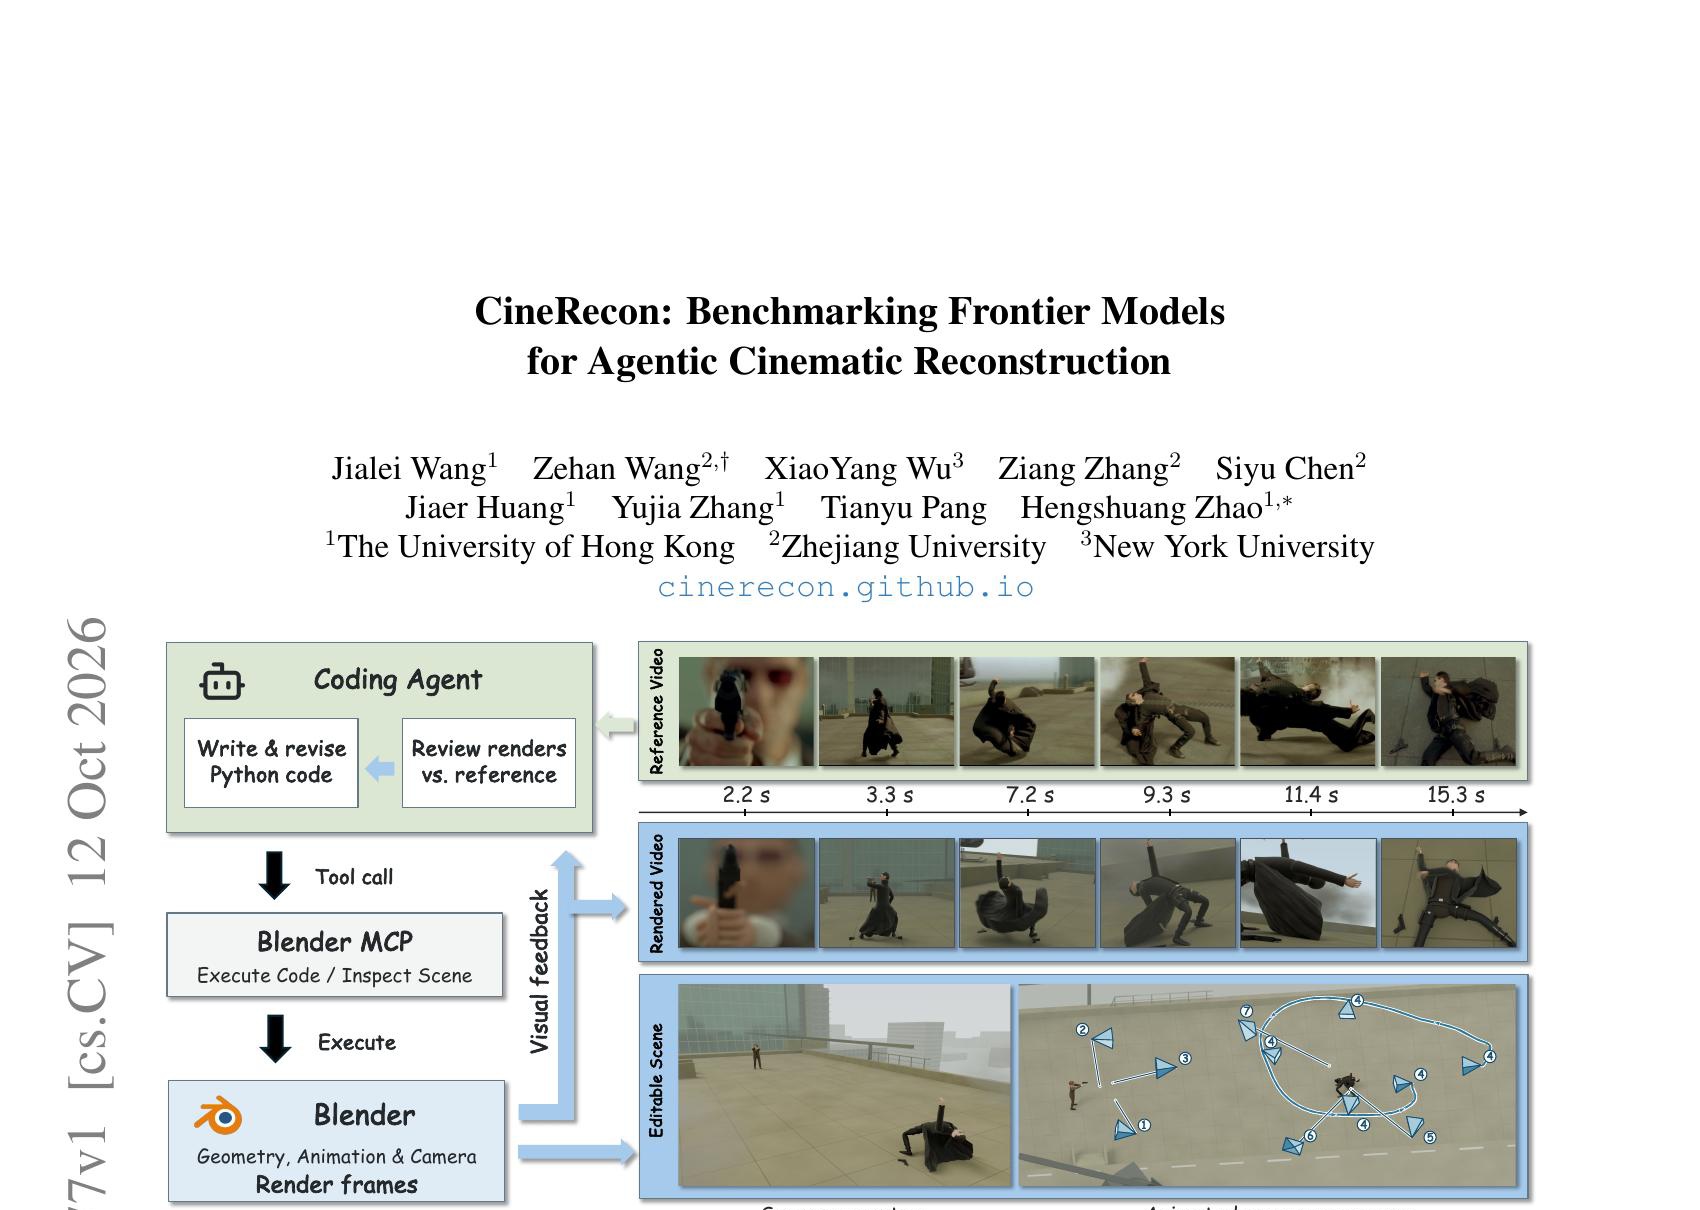
79. WAVE-0: Bridging VLA Policies and WAMs with Lightweight Latent Future Prediction
🔑 Keywords: Vision-language-action, World action models, WAVE-0, Latent world model, Robotics
💡 Category: Robotics and Autonomous Systems
🌟 Research Objective:
– To develop a framework, WAVE-0, that bridges vision-language-action (VLA) policies with world action models (WAMs) through a lightweight latent world model for improved robotic manipulation.
🛠️ Research Methods:
– The introduction of WAVE-0, which connects pretrained VLAs with explicit future predictions, using a 257M world model that converts latent action plans into future representations, aiming to unify latent planning and action generation.
💬 Research Conclusions:
– WAVE-0 demonstrated high success rates in various benchmarks and significantly improved real-world task success rates, showcasing strong manipulation performance and generalization across diverse distribution shifts.
👉 Paper link: https://huggingface.co/papers/2610.18568
80. A Decade in a Day: Synthesizing Agent-Native Interfaces from Human-Oriented Software Evolution
🔑 Keywords: Large Language Model Agents, Discoverability, ANIS Framework, Interface Properties, Goal-level Commands
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The study investigates which interface properties make desktop software more accessible for large language model agents.
🛠️ Research Methods:
– Introduced DeskIF-Bench, a benchmark for assessing agent performance across software versions, and developed ANIS framework for synthesizing agent-native interfaces.
💬 Research Conclusions:
– New software releases consistently improve agent performance. ANIS enhances interface interaction, increasing success rates by 3.8% and 3.5% for two models and improving efficiency.
👉 Paper link: https://huggingface.co/papers/2610.15765
81. DeltaTTG: Training Multi-Turn Agents with a Token-to-Go Progress Meter
🔑 Keywords: Reinforcement Learning, DeltaTTG, Token-to-Go, Sample Efficiency, AI Native
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study introduces DeltaTTG, a method to enhance reinforcement learning with verifiable rewards for multi-turn agents by utilizing a shared progress meter and minimal cost supervision.
🛠️ Research Methods:
– DeltaTTG employs the Token-to-Go (TTG) as a proxy for task completion effort, redistributing rewards during actor training without altering trajectory advantages, leveraging pre-recorded diverse policy trajectories.
💬 Research Conclusions:
– DeltaTTG improves performance on ALFWorld, PaperSearchQA, and BFCLv3 benchmark tasks over traditional baselines, enhancing average scores and maintaining training efficiency comparable to GRPO. The method also demonstrates better sample efficiency and robust out-of-domain performance.
👉 Paper link: https://huggingface.co/papers/2610.17666
82. FlashVSR+: Efficient Video Super-Resolution via Hybrid Attention and Reward-Yield Distribution Matching
🔑 Keywords: Video Super-Resolution, Diffusion Distillation, FlashVSR+, Preference Alignment, High-Resolution Efficiency
💡 Category: Computer Vision
🌟 Research Objective:
– To enhance video super-resolution models for more efficient high-resolution inference and better alignment with human preferences.
🛠️ Research Methods:
– Develop FlashVSR+ with hybrid attention architecture, optimizing both strong locality and sparse global interactions.
– Introduce a novel training strategy, Reward-Yield Distribution Matching Distillation (Ry-DMD), to align model output with human preferences.
💬 Research Conclusions:
– FlashVSR+ achieves significant improvements in inference speed and memory usage, allowing efficient 4K video super-resolution.
– Ry-DMD successfully integrates user preferences without compromising on model generalization, showcasing improvements in both VSR and T2I generation.
– The release of code, models, and training data provides valuable resources for further research in this domain.
👉 Paper link: https://huggingface.co/papers/2610.17552
83. Learning How to Remember: Memory Modality Selection for GUI Agents
🔑 Keywords: vision-language models, GUI agents, memory augmentation, SwitchMem
💡 Category: Multi-Modal Learning
🌟 Research Objective:
– The study explores the impact of memory modality in vision-language models (VLM) for GUI agents and evaluates if a single memory modality remains optimal across interaction steps.
🛠️ Research Methods:
– Conducts a systematic analysis of memory representation strategies employing an adaptable routing framework called SwitchMem that dynamically switches between textual and visual memory modalities.
💬 Research Conclusions:
– The research concludes that memory modality should be dynamically adjusted at each interaction step, as demonstrated by SwitchMem’s performance, which surpasses traditional static memory approaches across multiple GUI benchmarks.
👉 Paper link: https://huggingface.co/papers/2610.17928
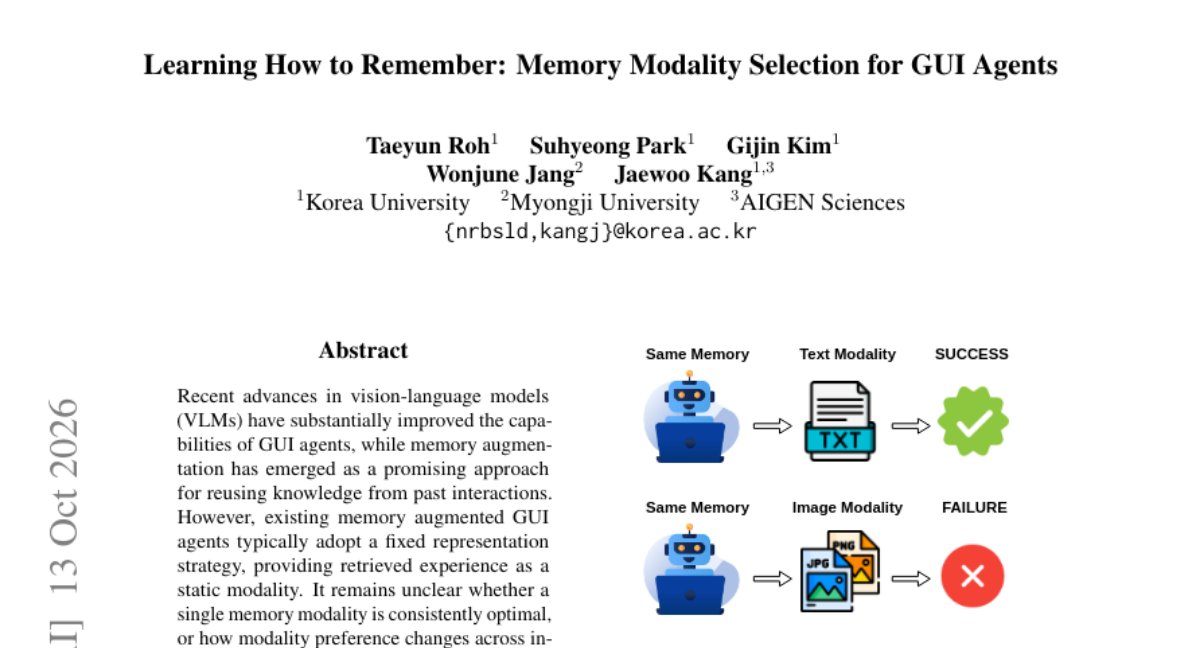
84. AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers
🔑 Keywords: Diffusion Transformers, full attention, Structural Distortions, AReA
💡 Category: Generative Models
🌟 Research Objective:
– To address the challenges in generating high-resolution images using Diffusion Transformers by identifying the limitations of uniform full attention and proposing an enhanced mechanism.
🛠️ Research Methods:
– AReA, a novel training-free attention mechanism, is introduced. It evolves its receptive field from coarse to fine during the denoising process, transitioning from global to local attention.
💬 Research Conclusions:
– AReA outperformed state-of-the-art training-free baselines across various target resolutions and models, proving to be faster and more efficient without requiring additional parameters or training.
👉 Paper link: https://huggingface.co/papers/2610.17227
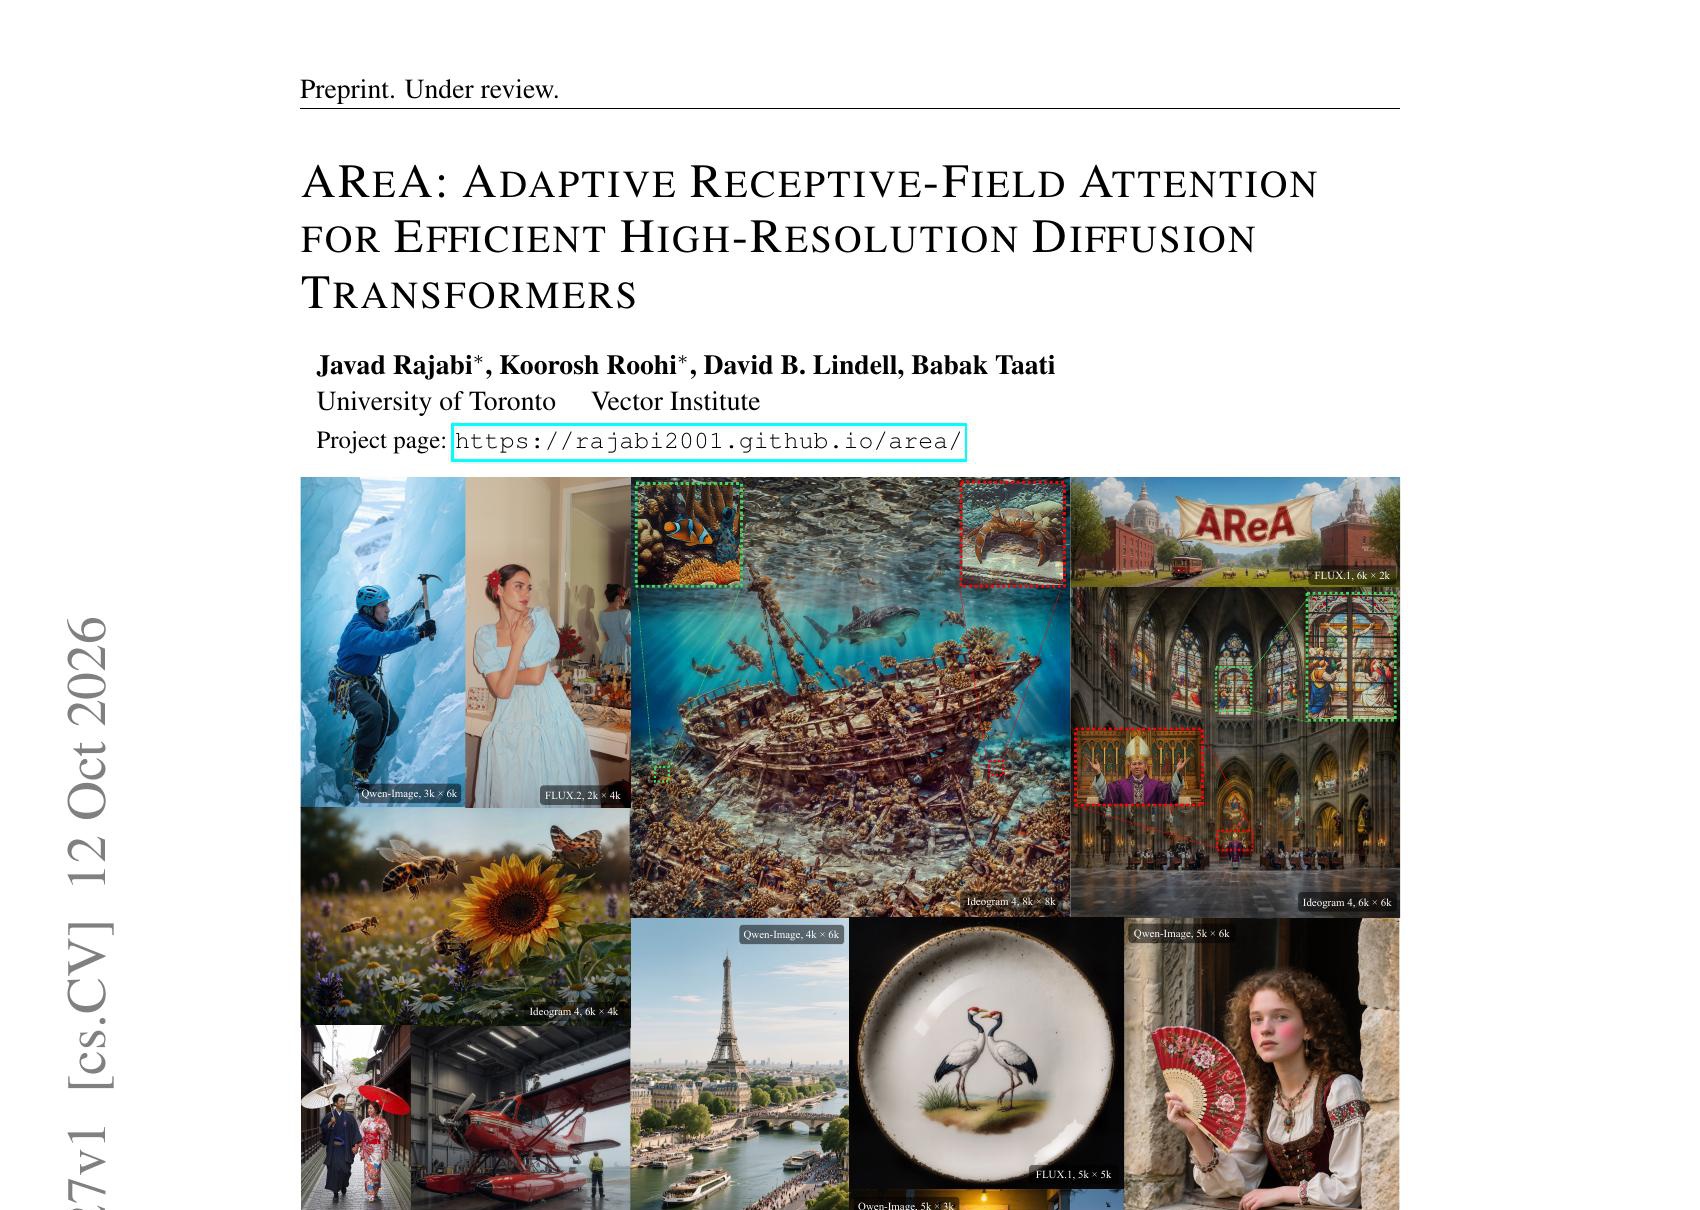
85. EviScene: Beyond “Is It AI?” for Agentic Image Factuality Assessment
🔑 Keywords: Image Factuality Assessment, EviLens, EviScene, Multimodal ReAct, Evidence-Grounded Explanation
💡 Category: Computer Vision
🌟 Research Objective:
– The study aims to introduce the task of Image Factuality Assessment and develop a system capable of providing verdicts with evidence-grounded explanations for whether an image’s depiction is factually supported or refuted.
🛠️ Research Methods:
– The paper introduces EviLens, a benchmark dataset, and develops EviScene, a multimodal ReAct agent that integrates visual inspection, external retrieval, and evidence analysis, refining questions during investigation. The model is trained using supervised fine-tuning and on-policy self-distillation to achieve higher accuracy and sufficiency rates.
💬 Research Conclusions:
– The Qwen3.5-9B agent demonstrates a balanced accuracy of 79.05% and a Strict Evidence Sufficiency Rate (SESR) of 52.26% on the test set, surpassing the performance of the base agent, indicating improved factuality assessment capabilities.
👉 Paper link: https://huggingface.co/papers/2610.14609
86. UltraBERT: Beyond the Limit of BERT Pre-Training
🔑 Keywords: bidirectional encoders, large language models, UltraBERT
💡 Category: Natural Language Processing
🌟 Research Objective:
– The study aims to enhance encoder performance by revisiting training design choices to optimize performance on both classification and retrieval tasks.
🛠️ Research Methods:
– The research examines the effects of pretraining on encoder optimization, discovering optimal masking ratios and employing distillation with pruning to refine performance.
💬 Research Conclusions:
– It is concluded that encoder performance saturates after certain token limits, optimal masking ratios vary by task, and UltraBERT efficiently separates LM heads for different tasks, achieving state-of-the-art results on GLUE and BEIR benchmarks.
👉 Paper link: https://huggingface.co/papers/2610.15028
87. Scoring Higher, Answering Worse: Mitigating Reward Hacking in Rubric-Based RL via Protocol-Level Rubrics
🔑 Keywords: Rubric-based reinforcement learning, ProRubric, AI in Healthcare, Reward validity, Protocol-level Rubrics
💡 Category: AI in Healthcare
🌟 Research Objective:
– To propose and evaluate the use of Protocol-level Rubrics (ProRubric) in rubric-based reinforcement learning to improve the aggregation process and ensure better performance in clinical consultation scenarios.
🛠️ Research Methods:
– Implementation of a system that groups rubrics into protocol-level dimensions, where each dimension is validated as a whole rather than via a weighted sum; the grouping process is done offline without changing the optimizer.
💬 Research Conclusions:
– ProRubric enhances appropriateness by 10.8 points without losing rubric coverage and achieves the highest average performance across seven benchmarks. It demonstrates that policy effectiveness can be significantly improved by modifying rubric aggregation strategies.
👉 Paper link: https://huggingface.co/papers/2609.38847
88. ExeWorldBench: Benchmarking Code-Based Executable 3D World Modeling
🔑 Keywords: Executable World Modeling, ExeWorldBench, World Understanding, Causal Principles, AI Native
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The primary objective is to introduce ExeWorldBench, a novel benchmark designed to evaluate world understanding and executable realization through code-based 3D world construction.
🛠️ Research Methods:
– ExeWorldBench includes three challenging tasks: Mechanism Executability, Compositional Executability, and Intent-Driven Executable World Synthesis, each testing different aspects of executable world modeling.
💬 Research Conclusions:
– Extensive experiments reveal considerable limitations in existing models, highlighting the need for the development of more physically grounded and causally coherent world construction systems.
👉 Paper link: https://huggingface.co/papers/2610.15166
89. DoSA: Dots Sparse Attention
🔑 Keywords: Sparse attention, DoSA, Top-K selection, GPU implementation, AI Systems and Tools
💡 Category: AI Systems and Tools
🌟 Research Objective:
– The paper introduces DoSA (Dots Sparse Attention), a method aimed at making sparse attention computation conditional while maintaining exact token selection.
🛠️ Research Methods:
– The researchers developed techniques involving nonnegative head projections and joint residual bounds to create upper-bounds, used activation-informed aggregation for negative head adjustment, and established a certificate system for candidate scoring efficiency.
💬 Research Conclusions:
– The GPU implementation of DoSA accelerated processing by up to 2.74 times over SGLang and 1.69 times over LiteTopK for multiple languages and datasets. Additionally, it achieved significant speedups in end-to-end evaluation on GLM-5.2 and DeepSeek-V3.2 compared to baselines.
👉 Paper link: https://huggingface.co/papers/2610.13990
90. Vela: User Behavior as Supervision Sparks LLM Intelligence
🔑 Keywords: Large Language Models, User Behavior Data, Fine-tuning, Reinforcement Learning
💡 Category: Natural Language Processing
🌟 Research Objective:
– The paper aims to explore the integration of real-world user behavior data as a form of supervision to enhance the intelligence of large language models (LLMs), specifically in understanding user preferences, intent, and likely future actions over extended periods.
🛠️ Research Methods:
– Introduction of Vela, a framework that utilizes anonymized behavior records from 100,000 users to generate tasks and trajectories for training.
– Fine-tuning of the Qwen3.6-35B-A3B model on these tasks and implementing reinforcement learning after fine-tuning for improved performance.
💬 Research Conclusions:
– The application of real-world user behavior data leads to significant performance improvements, with up to 11.5 points increase in user-related tasks and an average of 4 points on general benchmarks.
– Post fine-tuning reinforcement learning further boosts performance, indicating that user behavior data is a potent source for advancing user-centered and broader LLM capabilities.
👉 Paper link: https://huggingface.co/papers/2610.14709
91. Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards
🔑 Keywords: Long-horizon agents, Tev-Gym, Progress-potential reward shaping (PPRS), Automated discovery, Recursive self-improvement (RSI)
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To enhance the training and performance of long-horizon agents through an innovative dataset and training recipe.
🛠️ Research Methods:
– Introduction of Tev-Gym, a dataset with verifiable, dense, progressive rewards for training long-horizon agents.
– Development of a training recipe using progress-potential reward shaping to convert progress metrics into dense per-step rewards.
💬 Research Conclusions:
– Training with the proposed recipe results in Tev-27B, which shows significant performance gains equivalent to high-level models like GPT-6 Astra and surpasses others in specific benchmark tests.
👉 Paper link: https://huggingface.co/papers/2610.18868
92. AesCode: Aesthetic Code Generation with Decoupled Cross-Modal Rewards
🔑 Keywords: AesCode, visual artifacts, reinforcement learning, Visual Graph Rubric
💡 Category: Generative Models
🌟 Research Objective:
– The study introduces AesCode, aiming to generate code that is aesthetically guided by images to enhance the creation of visual artifacts like slides and dashboards.
🛠️ Research Methods:
– Utilizes design graphs for coding representation and employs cross-modal rewards through reinforcement learning to improve spatial planning and aesthetic quality.
💬 Research Conclusions:
– AesCode, with reference images, significantly boosts visual quality, achieving performance comparable to advanced models like GPT-5.5 and Claude Opus 4.8.
👉 Paper link: https://huggingface.co/papers/2610.18860
93. Urbex: Agentic Spatial Grounding for City-Scale 3D Scenes
🔑 Keywords: Urbex, 3D grounding, Reinforcement Learning, City-scale
💡 Category: Reinforcement Learning
🌟 Research Objective:
– To propose Urbex, an agentic vision-language framework for city-scale 3D grounding, by formulating the task as an active spatial search instead of candidate ranking.
🛠️ Research Methods:
– Use of a VLM agent in an interactive multi-view environment.
– Optimization of tool-use policy with reinforcement learning on the CityRefer dataset.
💬 Research Conclusions:
– Urbex achieves superior performance on metrics such as Hit@1 and IoU compared to baselines.
– Supports candidate-free grounding and demonstrates faster processing.
– Exhibits improved cross-scene robustness in zero-shot settings on STPLS3D-Refer.
👉 Paper link: https://huggingface.co/papers/2610.18356
94. Agent-Reflex: Teaching Language Agents to Act Reflectively
🔑 Keywords: Large language models, reflection learning, Agent-Reflex, reinforcement learning, long-horizon reasoning
💡 Category: Reinforcement Learning
🌟 Research Objective:
– The study aims to enhance long-horizon reasoning in large language models through a framework called Agent-Reflex, targeting improvement in reflection learning and failure recovery.
🛠️ Research Methods:
– The research employs a three-stage training framework: Environment Reflection Skill Discovery, Reflective Supervised Fine-Tuning, and On-Policy Reflective Policy Optimization, to incentivize proactive reflection in agents.
💬 Research Conclusions:
– Agent-Reflex demonstrated significant improvements in large language models’ robustness, surpassing existing baselines in noisy settings and maintaining stable training dynamics, proving the framework’s scalability and effectiveness on various benchmarks.
👉 Paper link: https://huggingface.co/papers/2610.17953